Smoke vs Regression Testing: Differences, and Smart Smoke for CI

Smoke testing is a quick, shallow check that a new build works at all (it starts, logs in, and its critical paths respond), while regression testing re-runs a broad set of tests to confirm that existing behaviour did not break after a change. Smoke runs on every build in minutes to decide whether deeper testing is worth starting; regression runs before a release, or nightly, and can take hours.
| Smoke testing | Regression testing | |
|---|---|---|
| Question it answers | Is this build stable enough to test? | Did this change break anything that used to work? |
| Scope | A few critical paths | Broad, often the full suite |
| When | Every build or PR | Before release, nightly, or on risky changes |
| Duration | Minutes | Up to hours |
| Failure means | Reject the build early | Fix or accept a known regression before shipping |
The trouble starts when the regression suite grows faster than your CI budget. That is the problem Smart Smoke solves.
Your agents have been writing tests for a few months, and now you have 500+ E2E tests taking an eternity to run. Sounds familiar?
Say hello to Smart Smoke.
With agents authoring tests en masse, the problem has changed. Coverage gaps close fast—but:
- Your CI bill keeps growing as you run the full suite on every PR
- Worse, you wait hours before knowing if anything broke
Today, smoke suites are often manually managed. Tag lists. Folder filters. A @smoke set someone curated last quarter. That leaves a lot of useful signals on the table—especially as test suites grow at an unprecedented pace.
What really interested me here—as a lover of algorithms—was that this is essentially a classic optimization problem:
Given N minutes, how do you maximize semantic coverage + PR impact?
First: find what the PR can break
An agent identifies the tests relevant to the change—impacted scenarios from your plans, linked SmartTests via scenario annotations, plus anything newly authored on the branch. That related set lands in plans/smart-smoke/<branch>/related-tests.json.
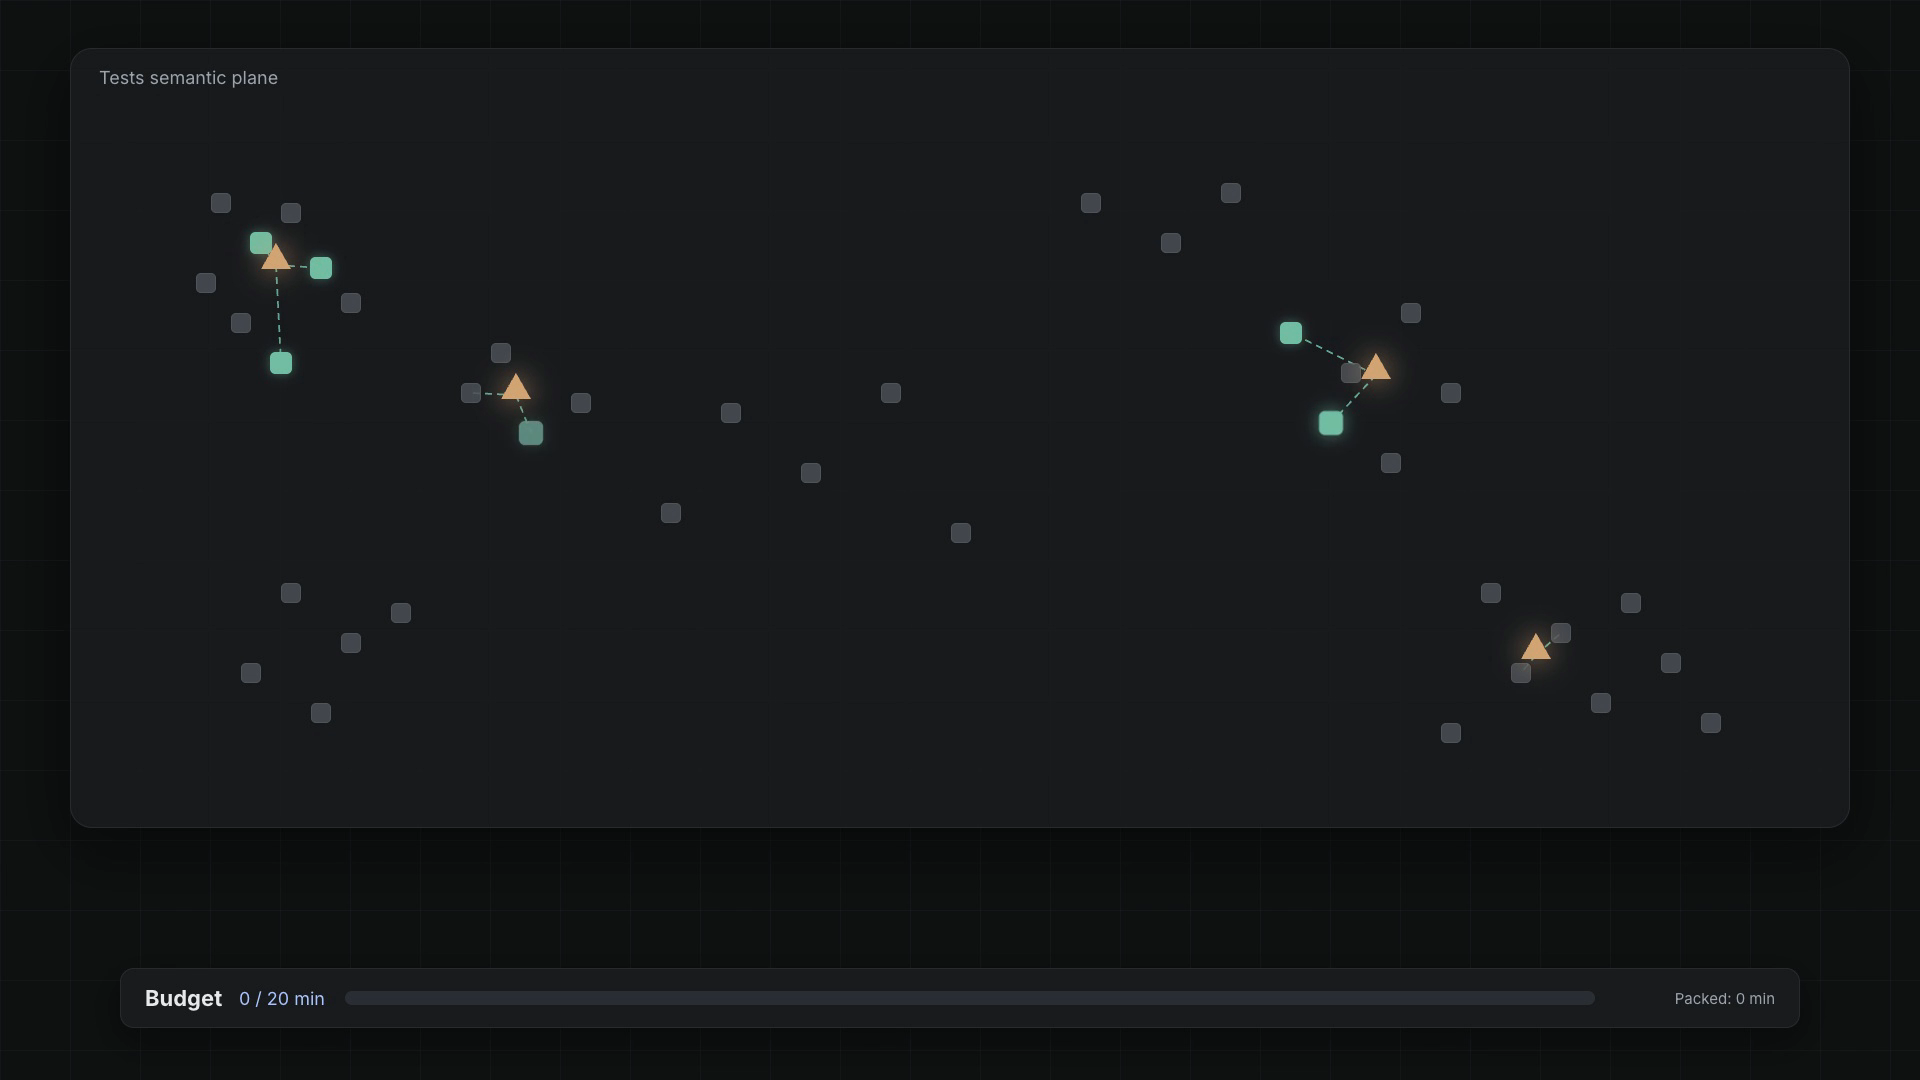
That’s the seed. Then comes the fun part: covering as much ground as possible.
Paint the canvas within a fixed budget
Imagine your tests laid out as nodes on a semantic canvas. The problem becomes:
Paint the canvas by selecting test nodes to maximize the covered spread—within a fixed time budget.
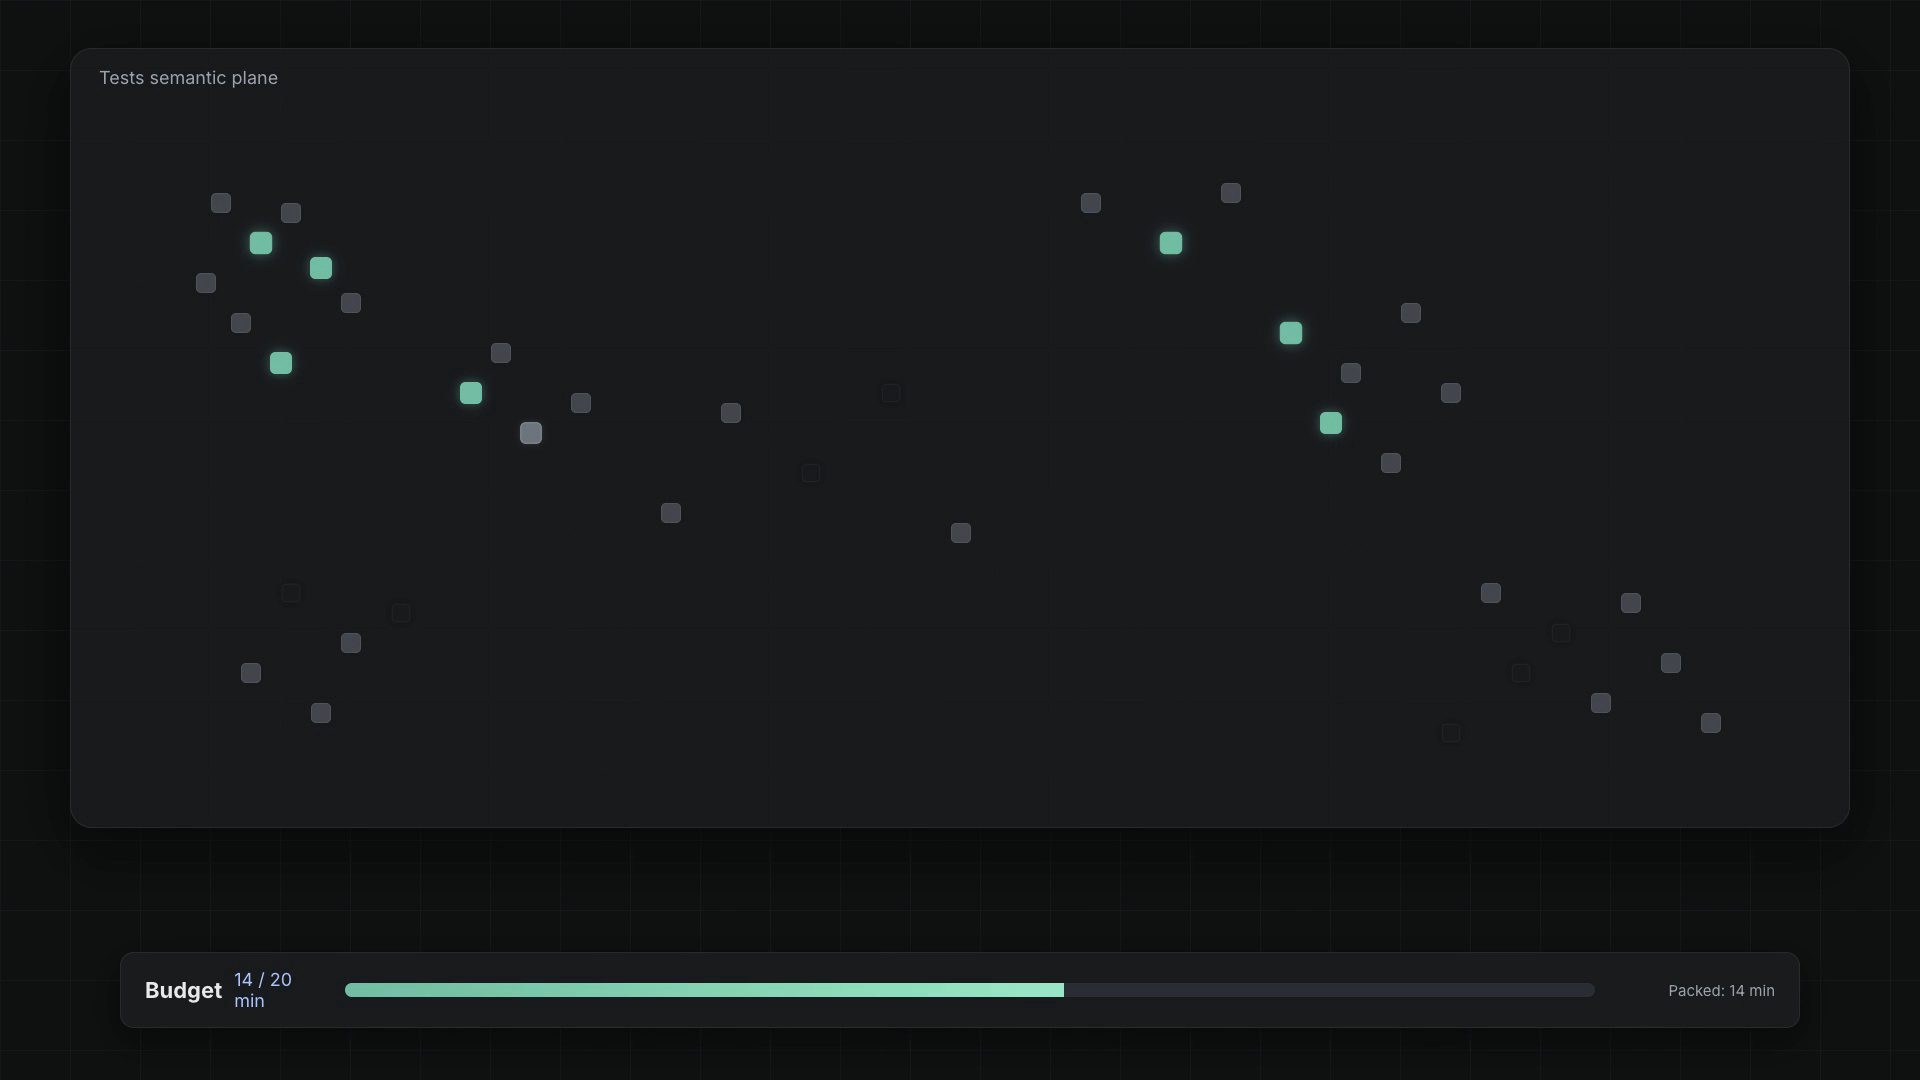
We don’t just grab the nearest cluster. We iteratively pick the next test that adds the most new ground—so selection spreads across the plane instead of camping in one corner.
Then weigh the terrain
Pure geometry isn’t enough. We weigh the terrain using signals like scenario priority, recency, test stability, execution time, historical failures—so packing prefers tests that are both informative and practical.
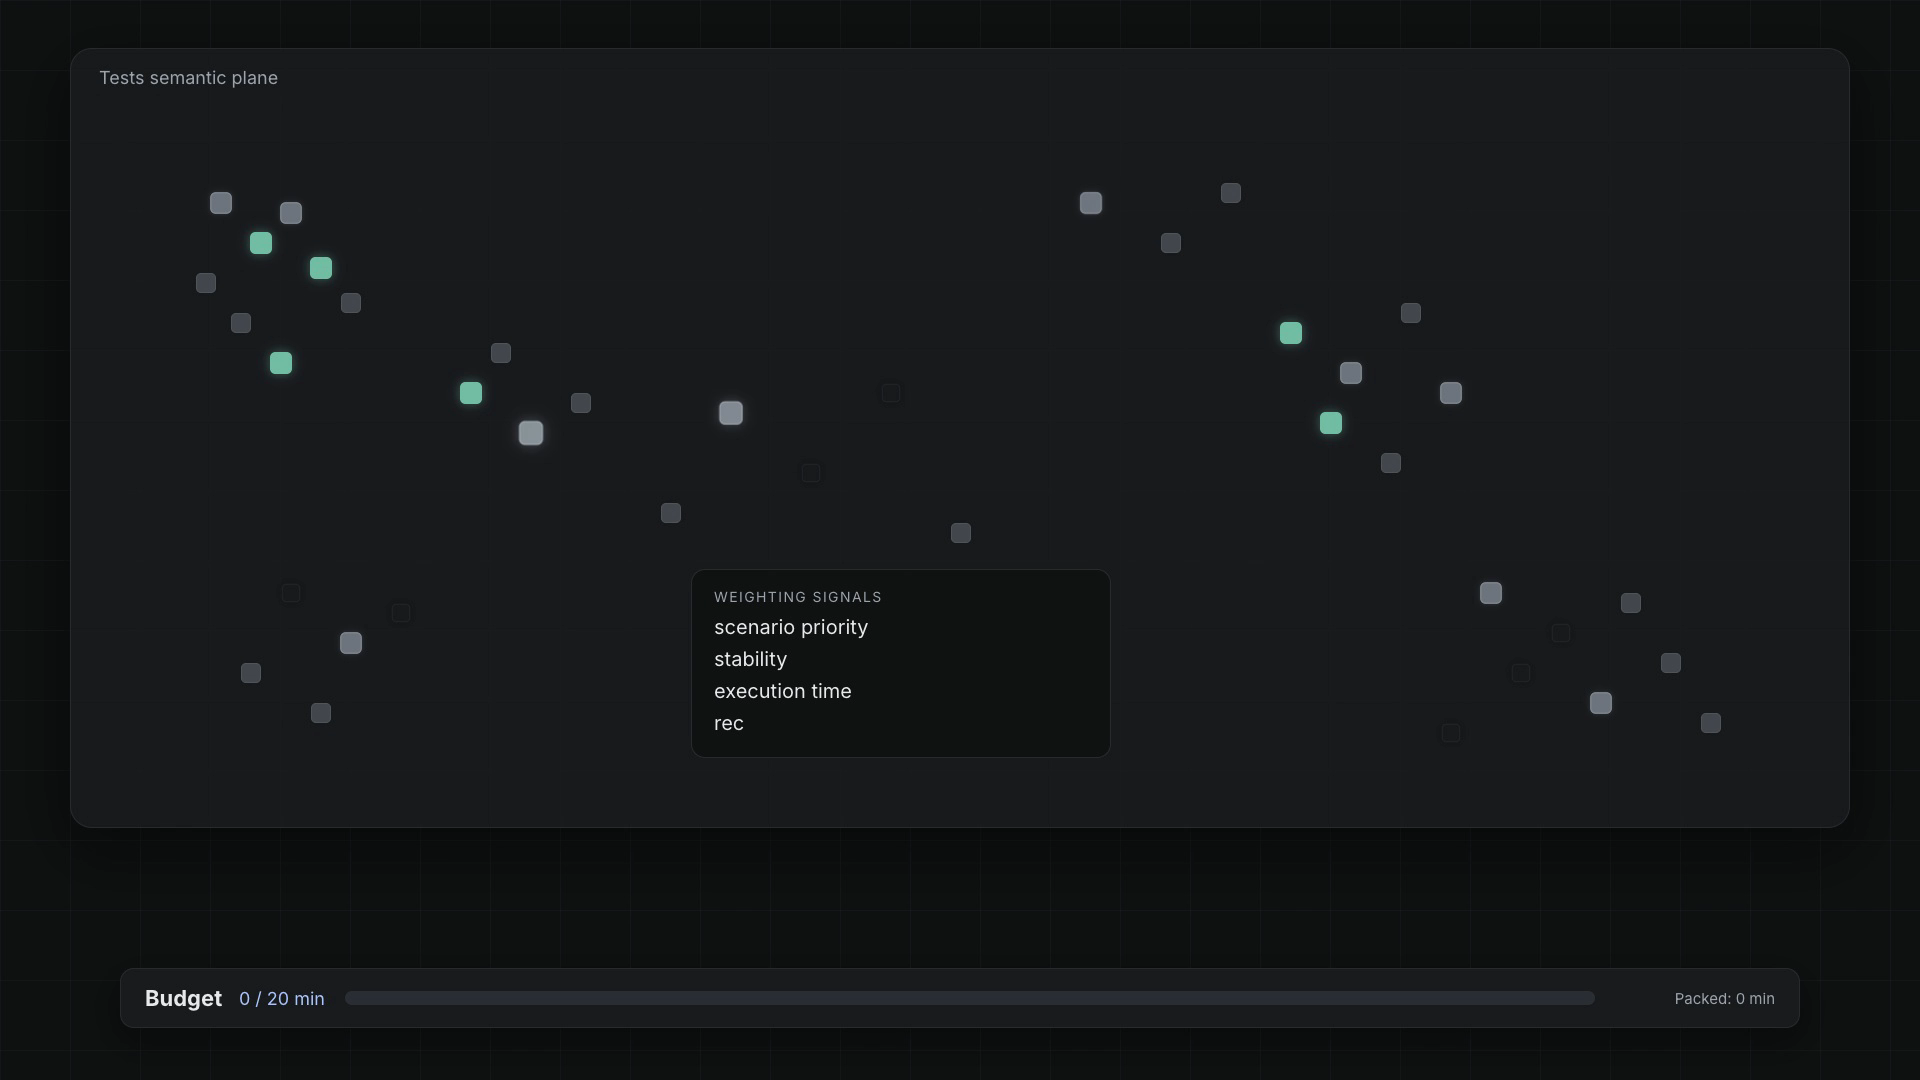
Seeds always include related tests, tagged smoke (e.g. @smoke), and newly authored branch tests. Packing fills whatever budget remains—until the bin is full.
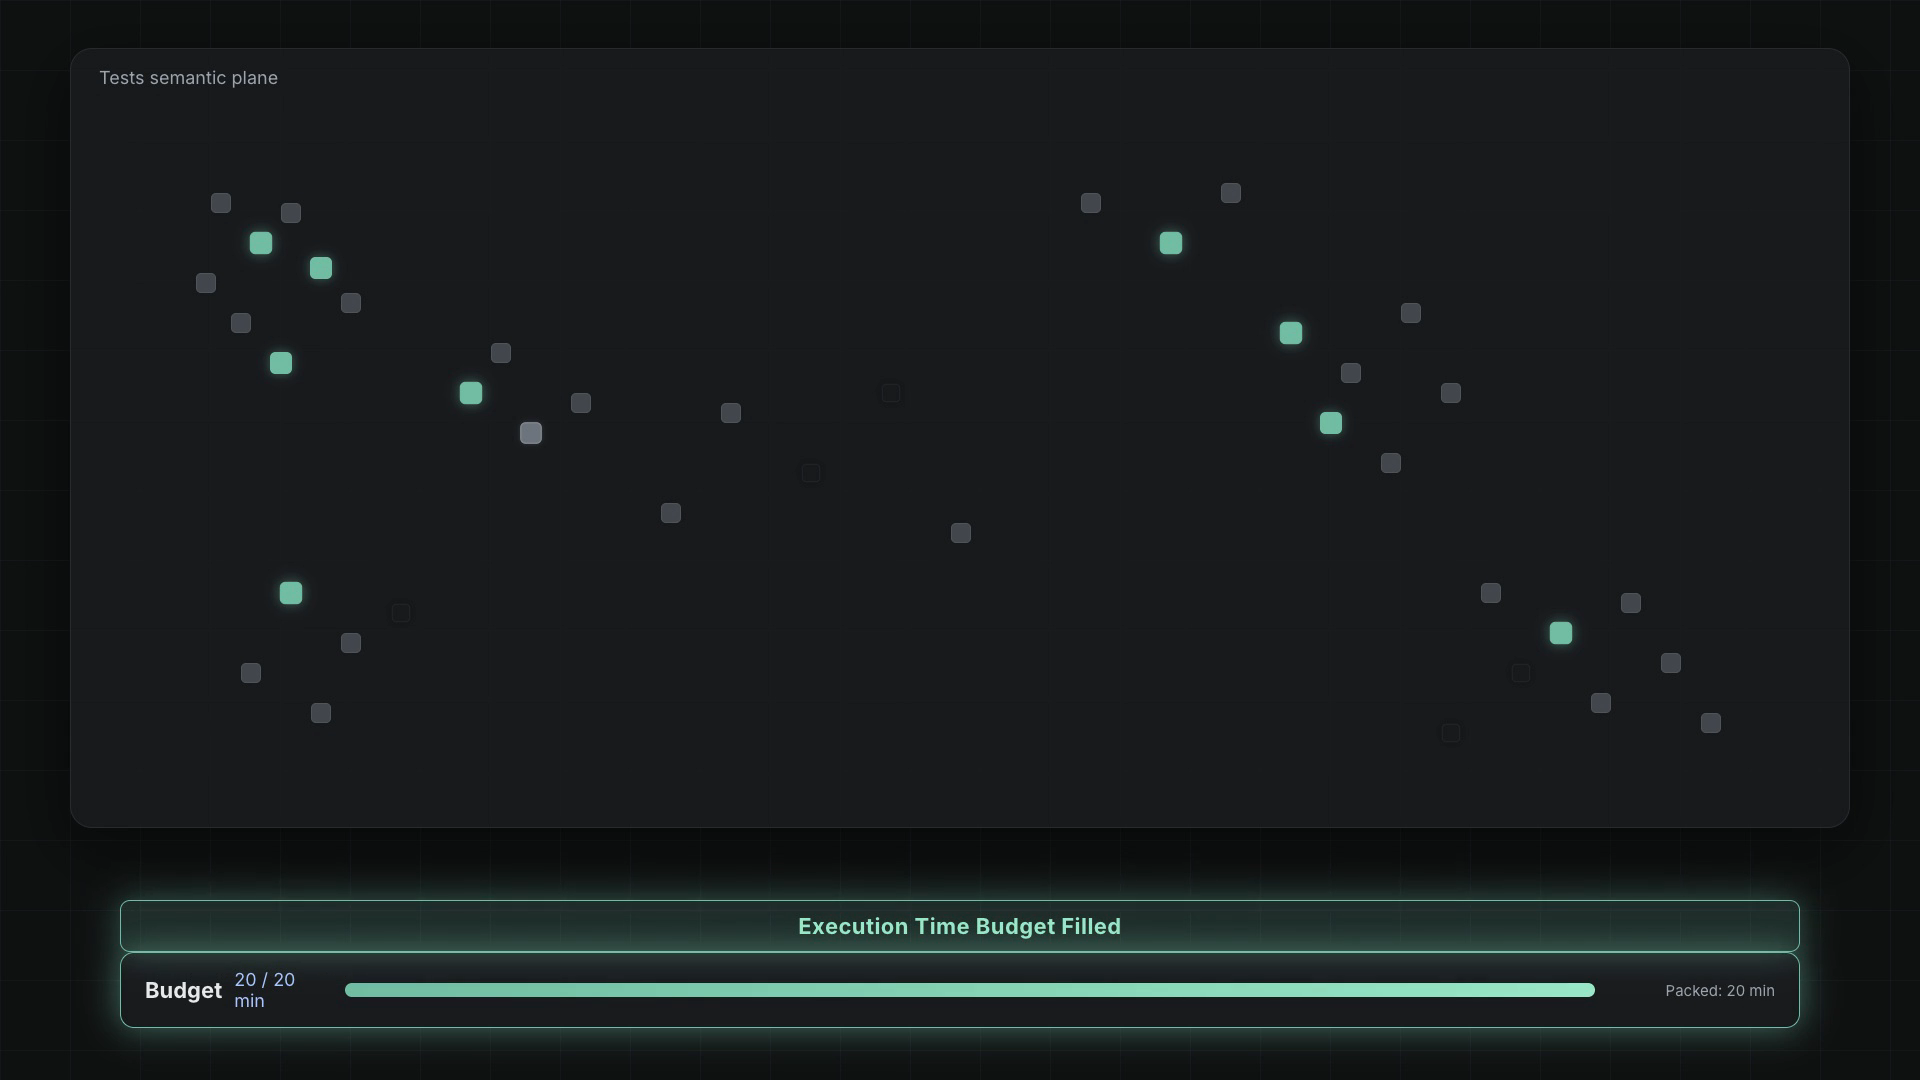
The result: the best subset of tests to run as smoke for a given PR—giving you the most confidence within a fixed time budget.
Less CI cost. Less waiting. More confidence.
Same Playwright command
Smart Smoke isn’t a new runner. You keep your SmartTests and the same npx playwright test—opt in per run:
export TESTCHIMP_SMART_SMOKE_ENABLED=true
# optional: time budget, suite %, tags, related-tests-only
npx playwright test
Non-selected tests skip with reason smart-smoke (distinct from an explicit test.skip).
| Mode | Best for |
|---|---|
| Related-tests-only | Tight PR confidence (safe agent default) |
| Budgeted smoke | Broader ROI within a time / count / suite-% cap |
It plugs into /testchimp test as Phase 5, or standalone via /testchimp run smart smoke.
Full reference: Smart Smoke Runs · How it works · Configuration.
Plugin: @testchimp/playwright (≥ 0.2.20).
Related QA guides
- Playwright alternatives compared
- Cypress vs Playwright
- Stripe test cards for Playwright E2E
- Requirements traceability matrix (RTM) template
- Test plan template in Markdown
Smoke responsibly.