22 posts tagged with "Build in Public"

Building TestChimp in the open

View All Tags

API Contract Governance: Cover What Your Spec Promises

· 6 min read
Nuwan Samarasekera
Founder & CEO, TestChimp

TL;DR: We’ve shipped API contract governance in TestChimp. Point us at your OpenAPI roots, opt in to API payload capture on SmartTest runs, and the APIs surface shows which operations—and which request/response fields and status codes—your automation actually exercised. Uncovered holes become Create issue, Create test, or Ignore gap—accountable work, not a spreadsheet of “we should cover that someday.”


The contract nobody audits​

Your OpenAPI (or Swagger) file is not documentation fluff. It is the business contract of the product: methods, paths, request shapes, response codes, and fields clients depend on.

UI E2E already touches that contract. Checkout hits POST /orders. Declined payment hits POST /payments. A rare enum or a 422 body? Often never.

Without a contract lens, teams hit the same failure modes:

Failure modeWhat goes wrong
Happy-path blind spotsGreen UI suites; error enums, optional filters, and rare response codes never run
Spec driftTraffic hits paths or fields the OpenAPI root never declared
Silent API debt“We have E2E”—whole services still have zero covering tests
Unowned gapsSomeone notices a hole; nothing is filed, authored, or consciously deferred

API contract governance is not a separate API-testing product. It is the audit and triage layer that turns traffic your SmartTests already generate into accountable coverage of the contract.

Full product guide: API Contract Governance.


How it works​

Three inputs. One surface.

  1. Discover the contract — Configure OpenAPI root path(s) from your connected repo (APIs → Configure). TestChimp parses them into services and operations.
  2. Observe traffic — Run SmartTests with TESTCHIMP_ENABLE_API_CAPTURE=1 (and @testchimp/playwright ≥ 0.2.17). Matching HTTP interactions upload with the batch; coverage denorm runs after—not on the hot ingest path.
  3. Govern gaps — List view for the portfolio; detail view for schema fields and response codes. From any hole: file an issue, copy an agent prompt to create/update tests, or ignore the gap when it is intentional.

Capture is off by default so ordinary runs stay light. Opt in when you want Operations coverage—same pattern as other optional runtime features. Setup detail: Set up API contract governance and the runtime plugin.


From endpoint scores to schema fields​

The APIs list is the portfolio view: service picker, coverage-band summary, method/path, spec-defined vs observed-only, coverage score, latency, covering-test chips.

Click a row and you get the interesting part—field-level truth:
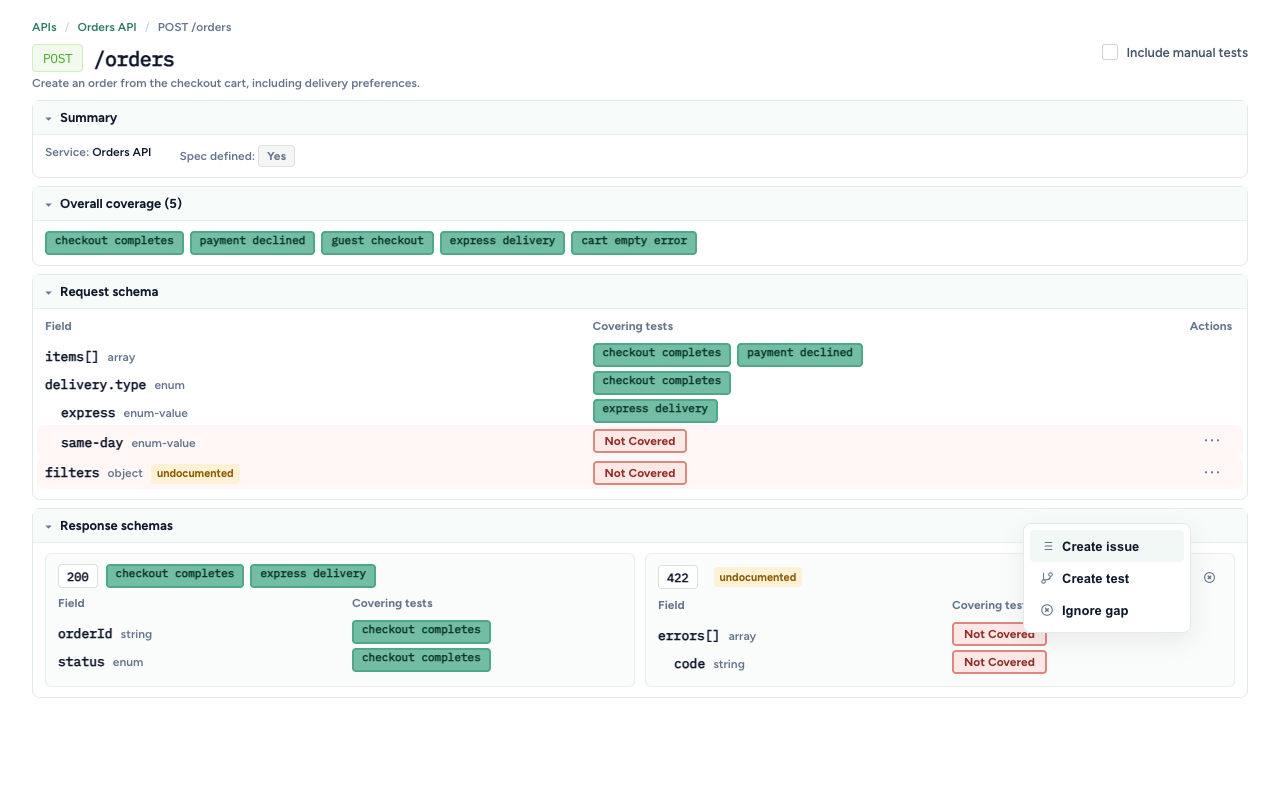
API operation detail with request schema tree, undocumented fields, and Create issue / Create test / Ignore gap

  • Request schema and query parameters with covering tests per field
  • Response schemas nested by status code
  • undocumented tags when traffic (or denorm) sees a field or code the OpenAPI root never declared
  • Empty covering tests when the contract exists but automation never exercised it

That is the difference between “we hit /orders” and “we never sent delivery.type = same-day, and nobody owns that hole.”

List and detail walkthroughs: Operations list · Operation detail.


Governance that sticks: issue, test, or ignore​

Coverage without triage is another dashboard nobody opens.

Wherever coverage is missing—operation, field, or response code—TestChimp offers the same decision set:

ActionWhen to use
Create issueTrack the gap as work—pre-filled title/description with method, path, operation id, and field or response code
Create testCopy an agent prompt scoped for /testchimp create tests—agents may update existing UI or API specs, not only invent a dedicated api/ folder
Ignore gapAcknowledge intentional out-of-scope or deprecated surface without filing or authoring

Agents already understand operation-id / field / response-code scopes. The UI just stops the gap from living only in someone’s head.


How this fits the rest of TestChimp​

If you’ve followed us:

  • Requirement quality governance hardens the plan contract before agents spend tokens
  • Release governance hardens the ship decision for a version
  • API contract governance hardens what your automation proved against the HTTP contract—the surface clients and integrations actually depend on

SmartTests remain the traffic source. Issues remain the backlog. Create-tests remains the authoring path. The APIs page is where contract debt becomes visible and governable—next to TrueCoverage for behaviour-aligned RUM, not instead of it.

Planned reality → tested reality → production reality. The API surface was the missing middle for teams whose “coverage” stopped at green UI journeys.


Frequently asked questions​

What is API contract governance in TestChimp?​

API contract governance maps OpenAPI operations to real and mocked SmartTest traffic so you can see endpoint and schema-field coverage, then triage gaps with create issue, create test, or ignore gap.

Do I need dedicated API tests?​

No. Coverage is inferred from HTTP traffic your SmartTests already generate when capture is enabled. You can still author dedicated API specs; the governance surface tracks both.

Why is my coverage empty after configuring OpenAPI?​

Parsing the spec discovers operations. Scores and covering tests need runs with TESTCHIMP_ENABLE_API_CAPTURE=1. Capture is off by default on purpose.

What does Ignore gap do?​

It marks an uncovered operation, field, or response code as intentionally ungoverned for now—without creating an issue or a test—so teams can acknowledge debt without false urgency.

Spec defined No vs undocumented—what’s the difference?​

Spec defined No on an operation means the whole method/path is missing from the OpenAPI root (observed in traffic only). An undocumented tag on a field or response code means that leaf was seen but not declared—classic contract drift.


Try it​

  1. Connect git and open APIs → Configure — select your OpenAPI root file(s)
  2. Wait for parse/sync; pick the service in the list
  3. Run SmartTests with TESTCHIMP_ENABLE_API_CAPTURE=1
  4. Refresh APIs — open a low-score or uncovered operation
  5. Create issue, Create test, or Ignore gap on the holes that matter

Start here:

Know the contract. Cover the edge cases—before unaudited branches ship.


Further reading​

TestChimp

Related posts

Semantic Canvas: See Your QA Knowledge by Meaning

· 6 min read
Nuwan Samarasekera
Founder & CEO, TestChimp

TL;DR: Existing QA tooling lets you follow explicit links only—story → ticket → test case → run, if someone remembered to wire them. Anything related by meaning but not linked stays invisible. TestChimp consolidates stories, scenarios, SmartTests, issues, and TrueCoverage events into a single embedding space. Semantic Canvas (in QA Brain) projects that space onto a 2D map so you can navigate neighborhoods, identify clusters, and surface related entities by conceptual similarity—then link near-misses, mark lookalikes distinct, or raise cleanup work from the sidebar.

Semantic Canvas in QA Brain


Last week we shipped InfiniTrace—walk the structural edges of your QA graph board by board.

That answers:

“What is linked to this story / test / event?”

Most of the industry stops there. Jira, TestRail, CI folders, coverage tools: if the edge wasn’t created, the relationship doesn’t exist. Keyword search helps only when titles share tokens. Paraphrases, cross-type near-misses, and quiet duplicates fall through the cracks—especially when agents author plans and tests at speed.

The sibling question traditional tools never answer:

“What looks like this—even if nobody linked it yet?”

Or:

“Which entities belong to the same conceptual neighborhood?”

Those need meaning, not another list sorted by updated-at.

TestChimp already maps every QA entity into a shared embedding space—beyond explicit links, into semantic proximity. Semantic Canvas is the surface that lets you see and navigate that space, next to InfiniTrace in QA Brain.


Introducing Semantic Canvas​

Semantic Canvas is a spatial map of your project’s QA knowledge—laid out by conceptual similarity.

Open QA Brain → Semantic Canvas tab (/brain?tab=semantic-canvas).

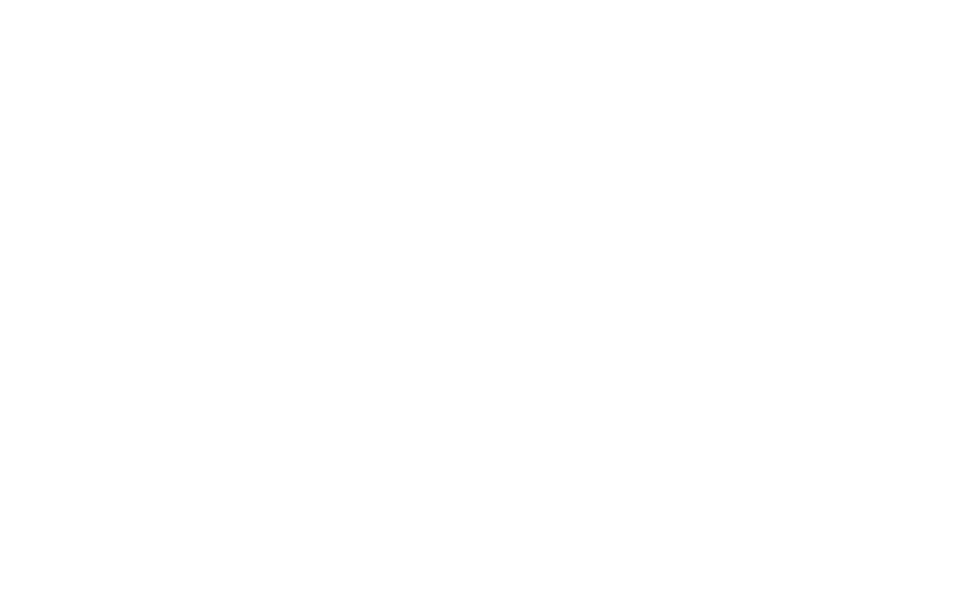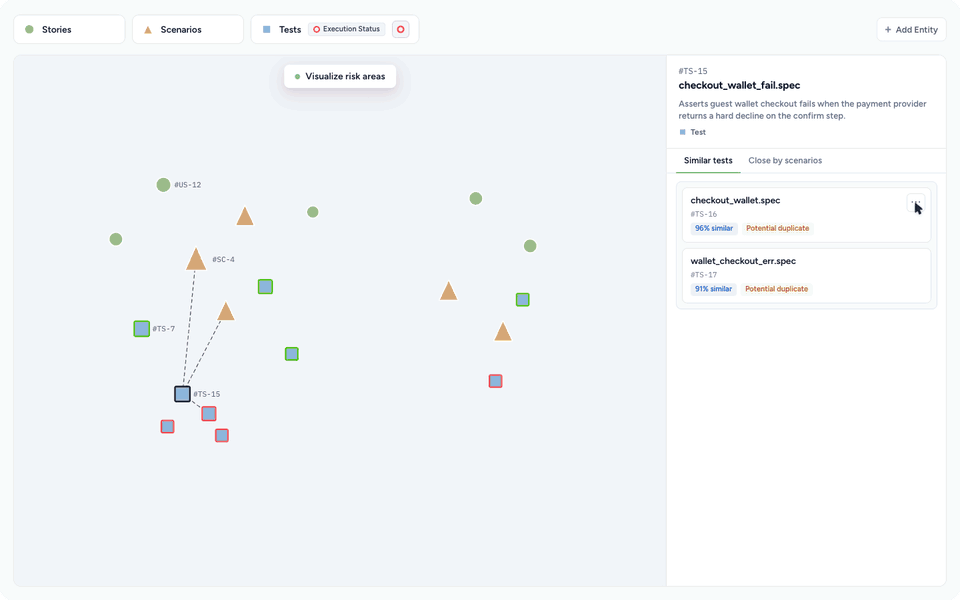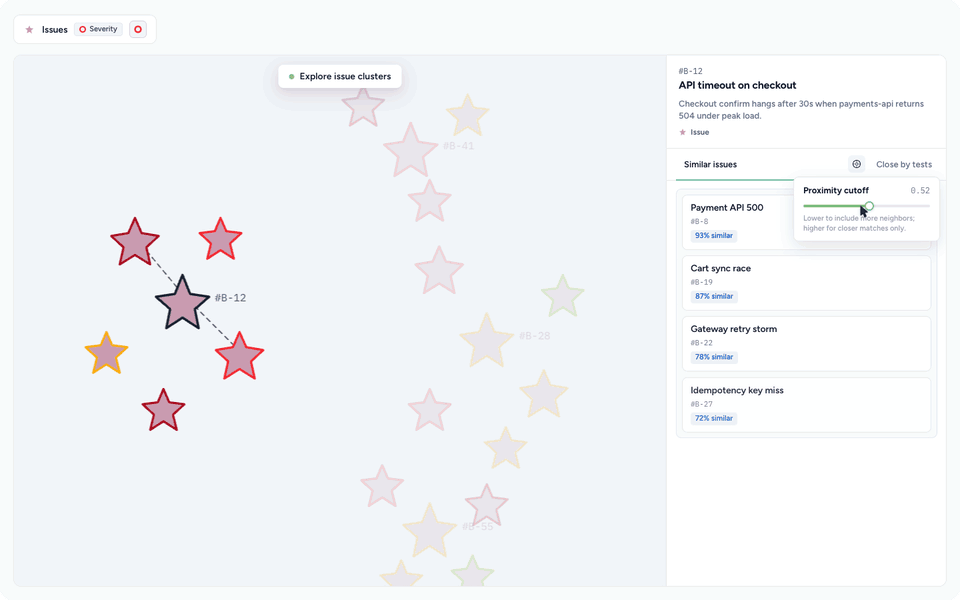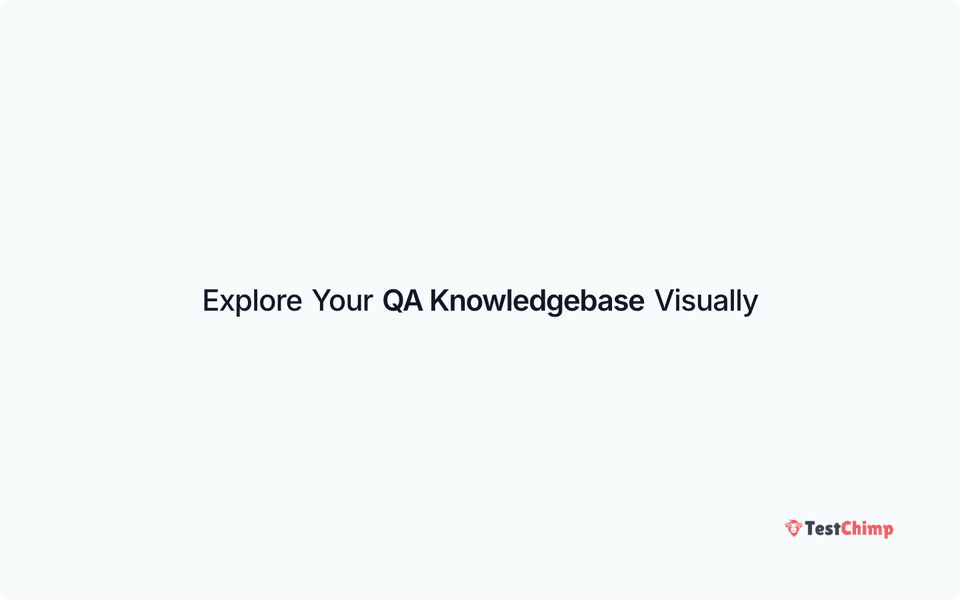
  1. Add the entity types you care about—Stories, Scenarios, Tests, Issues, Events
  2. Nodes land on a UMAP canvas: high-dimensional embeddings projected so local neighborhoods reflect cosine similarity
  3. Pan, zoom, filter, search (#US-12, titles, …)
  4. Click a node → the detail sidebar fills with cosine-ranked peers
  5. Link, mark distinct, create a duplicate-cleanup issue, or open details—in place

Deep links encode types, filters, border modes, and selection in ?locator= (with tab=semantic-canvas). “Look at this cluster” is a URL, not a screenshot.

Docs: Semantic Canvas.


What you can actually do with it​

A few use cases that show why a meaning map beats link-chasing alone:

Plan neighborhoods with live automation health​

Load Stories + Scenarios + Tests, paint test borders with latest execution status, and scan the map: requirement clusters with failing automation sitting right next to the plans they should cover—without walking each story’s link tree.

Duplicate / lookalike issue clusters​

Load Issues alone with severity borders. Twin bugs filed weeks apart with different titles collapse into neighborhoods. Open the sidebar, mark distinct where needed, or file cleanup when it’s a true duplicate.

Close semantic coverage gaps​

Put Scenarios + Tests (or Events + Tests) on one canvas. Select an unlinked scenario or hot TrueCoverage event → Close by tests ranks peers by cosine similarity → Link the near-miss that should have been wired months ago.

Requirement overlap before you plan more​

Plot Stories + Scenarios. Dense blobs often mean one idea wearing three titles—or a story that needs a scenario split—before you (or an agent) author more surface area.

TrueCoverage hotspots vs automation islands​

Add Events with has test coverage borders. Uncovered events that sit next to well-covered automation clusters are high-ROI gaps: instrumentation, missing emits, or a test that almost covers the behaviour.

We already open-sourced the suite-side cousin—Semantic Graph for Playwright folders. Semantic Canvas brings the same instinct into the product graph: not just tests vs tests, but cross-type meaning across your QA entities.

SurfacePrimary question
InfiniTraceWhat is structurally linked—and what’s a semantic near-miss on the next board?
Semantic CanvasWhat clusters by meaning—and what should I link or dedupe right here?

Same underlying entities. Same link rules. Two complementary ways to see the graph.


The sidebar is where the work happens​

The canvas orients you. The detail sidebar decides.

Select a node and you get accordion lists ranked by cosine similarity—not by how close the dots look after UMAP squashed the space into 2D (those can disagree; trust the scores for linking).

SectionJob
Similar <same type>Spot duplicates and over-similar peers
Close by <other type>Cross-type near-misses among types on the canvas

Tune a cosine cutoff per source→target pair. Raise it when you’re hunting true duplicates; lower it when you’re fishing for coverage gaps.

Then act:

  • Link — same model as InfiniTrace (including story↔scenario mappings and scenario annotation injection for scenario↔test)
  • Mark as distinct — teach the system “similar ≠ duplicate”
  • Create issue for duplicate — turn a lookalike pair into cleanup work
  • View details — read-only modal, then jump to the full page when you need to edit

If a card that looks nearby on the map falls below your cutoff, that’s not a bug—that’s the difference between a 2D sketch and embedding space. The sidebar keeps you honest.


Borders that mean something​

Pretty clusters aren’t enough. You need health overlays.

Per type, paint node borders with operational signal:

  • Latest execution status on tests / scenarios
  • Priority / severity and due status on stories, scenarios, issues
  • Has linked test on scenarios
  • Has test coverage on TrueCoverage events

Drop Stories + Scenarios + Tests with execution status on the tests, and the map stops being art: requirement neighborhoods with live automation health.

Or load Issues alone with severity borders—and watch lookalike bugs collapse into clusters you can actually triage.

Combine that with folder filters and status chips for sharper triage: failing tests next to the stories they should cover, severity islands of duplicate bugs, uncovered hot events next to automation islands.


Dashboards tell you what’s trending.

Atlas tells you where in the product structure something lives.

TrueCoverage tells you what real users do versus what tests cover.

InfiniTrace tells you how the pieces connect via explicit edges.

Semantic Canvas tells you what belongs together by meaning—even when the link was never created—and where quiet duplicates and near-misses still hide.

That’s the difference between knowing coverage is “82%” and seeing the blob of scenarios that are really one idea wearing three costumes.

Go open QA Brain → Semantic Canvas. Load Stories, Scenarios, and Tests with execution status—or Issues with severity—and click something you think is unique. If the sidebar shows a 90% twin you forgot existed… good. That’s the product working.

Full walkthrough: Semantic Canvas docs.
Pair it with: InfiniTrace.

InfiniTrace: Your QA Knowledge Graph, Finally Walkable

· 4 min read
Nuwan Samarasekera
Founder & CEO, TestChimp

TL;DR: QA revolves around a handful of core entities—stories, scenarios, tests, executions, issues, releases, screens—and they aren’t isolated: stories are verified by scenarios, scenarios by tests, tests produce executions, issues trace back to failures. For most teams, that knowledge lives scattered across disconnected tools, so following the thread means hopping platforms. TestChimp already consolidates those entities and relationships in one place. InfiniTrace (in QA Brain) turns that graph into an infinite board chain: pick a start, fan out to related types, and walk Linked vs Non-Linked entities—including semantic near-misses you can link in place.

InfiniTrace in QA Brain


The graph was always there​

Think about a single question a QA lead asks fifty times a week:

“What actually covers this story—and what didn’t we link yet?”

Or:

“This production event is hot in TrueCoverage. Which tests emit it?”

Or:

“This ExploreChimp journey found a bug. How does it connect back to plans and automation?”

Those aren’t dashboard questions. They’re traversal questions.

Traditionally, answering them meant hopping across Jira, a test runner, a coverage tool, an issue tracker—each holding a slice of the story, none holding the whole graph. TestChimp already consolidates those entities and their relationships in one platform: entity links, scenario annotations in SmartTests, SmartTest event emissions, exploration → journey structure, release and run context. The knowledge graph was real. What was missing was a way to walk it.

We’ve been cooking something for that.


Introducing InfiniTrace​

InfiniTrace is a horizontal link explorer for your project’s QA entities.

Open QA Brain in the sidebar → InfiniTrace tab.

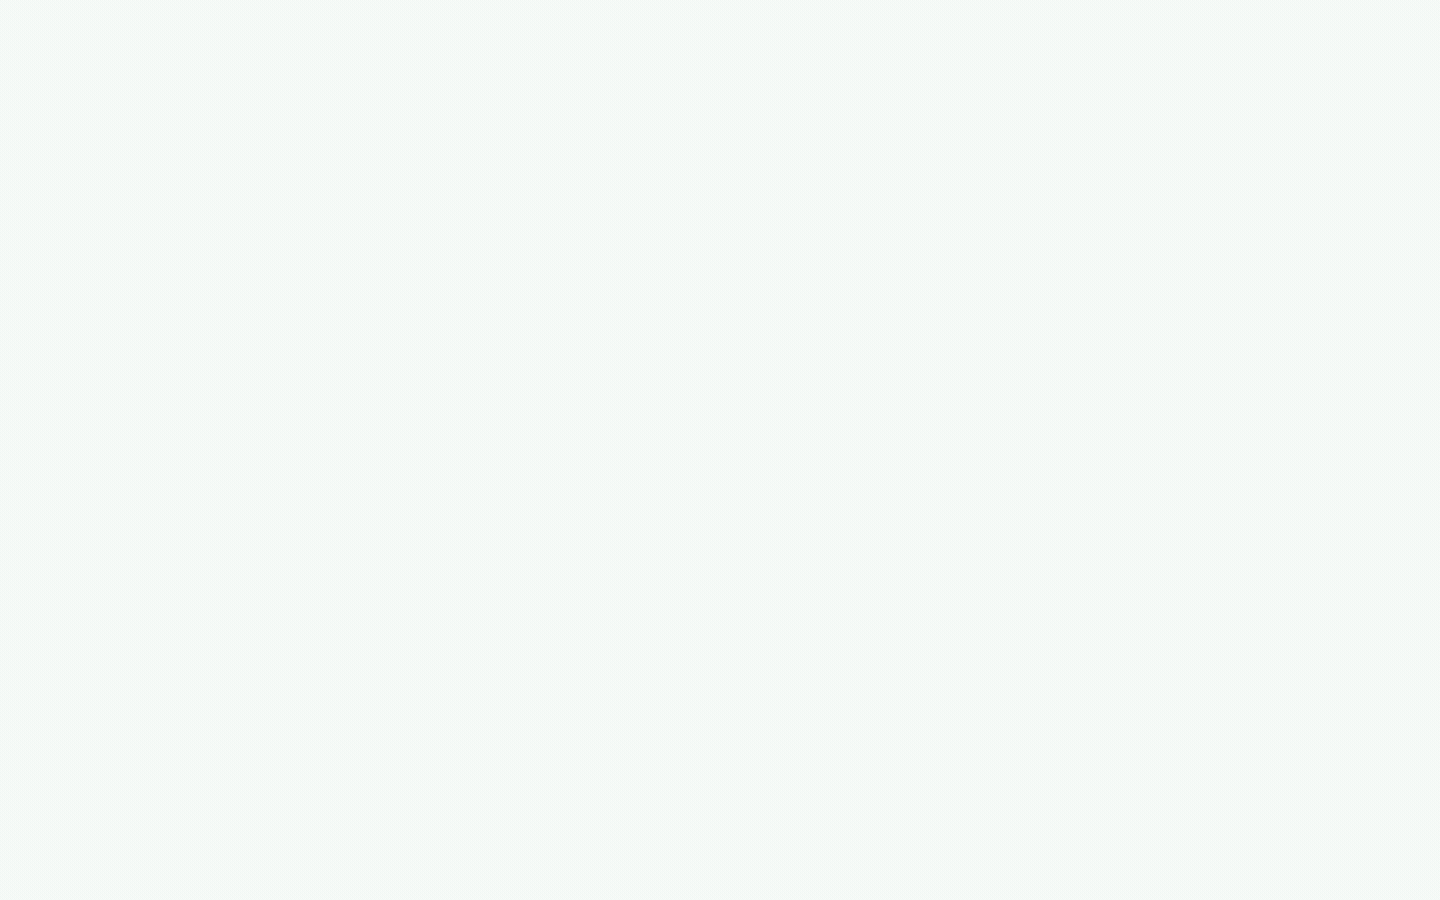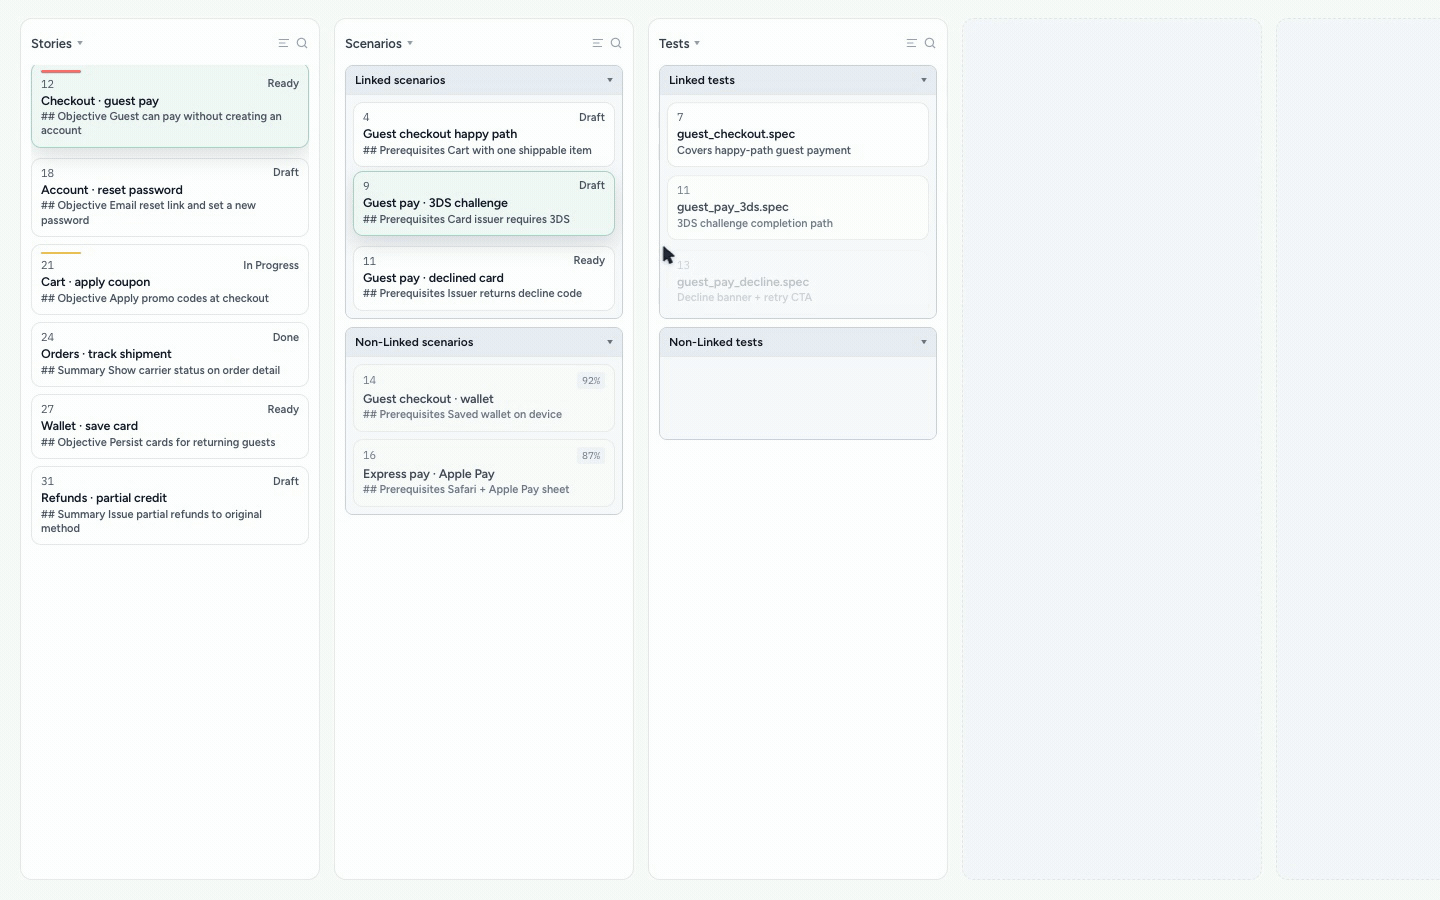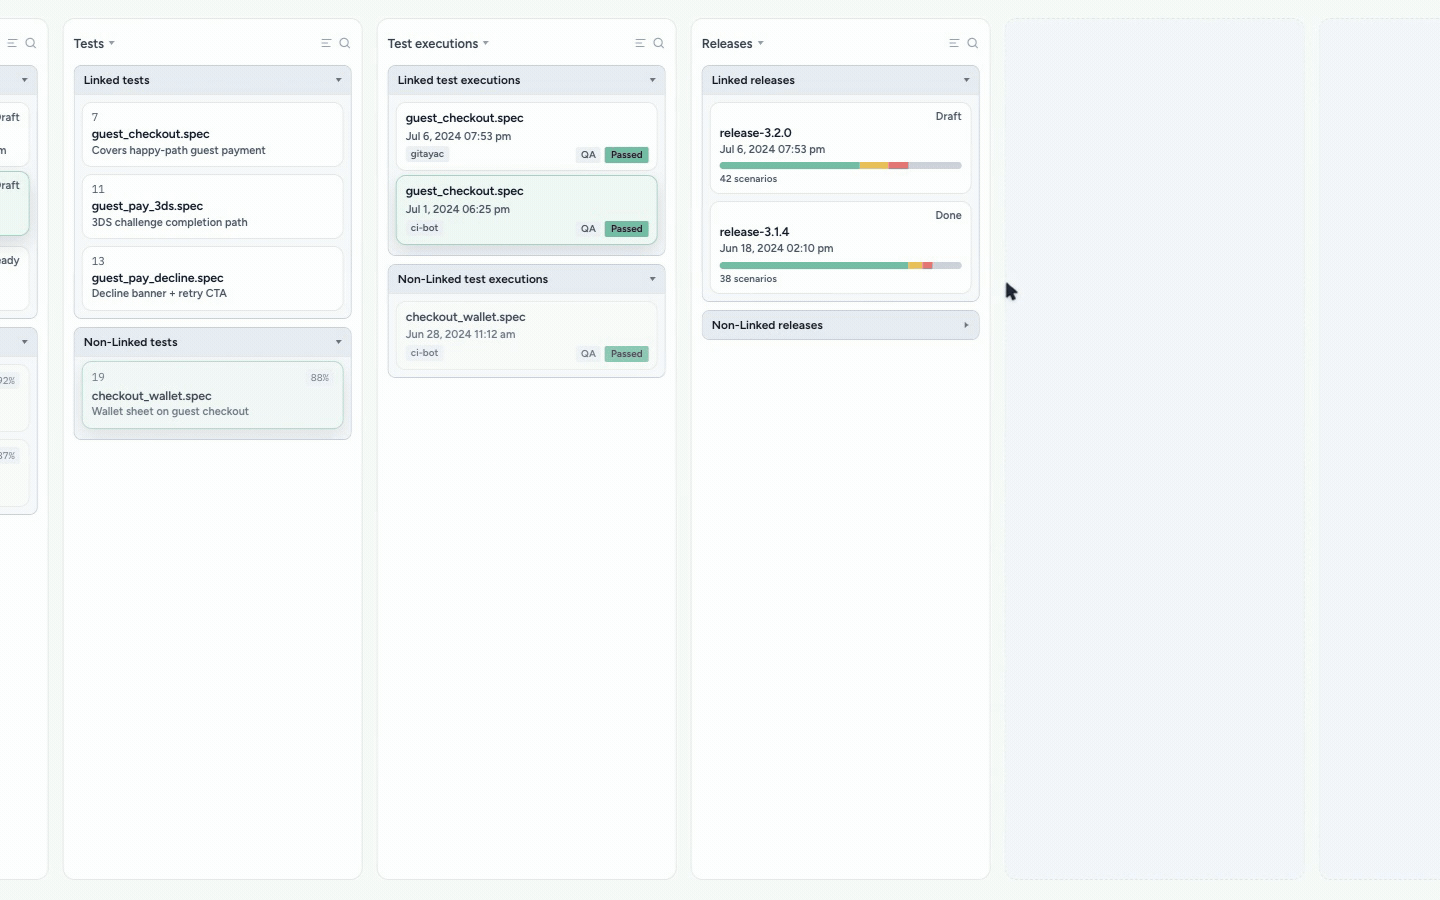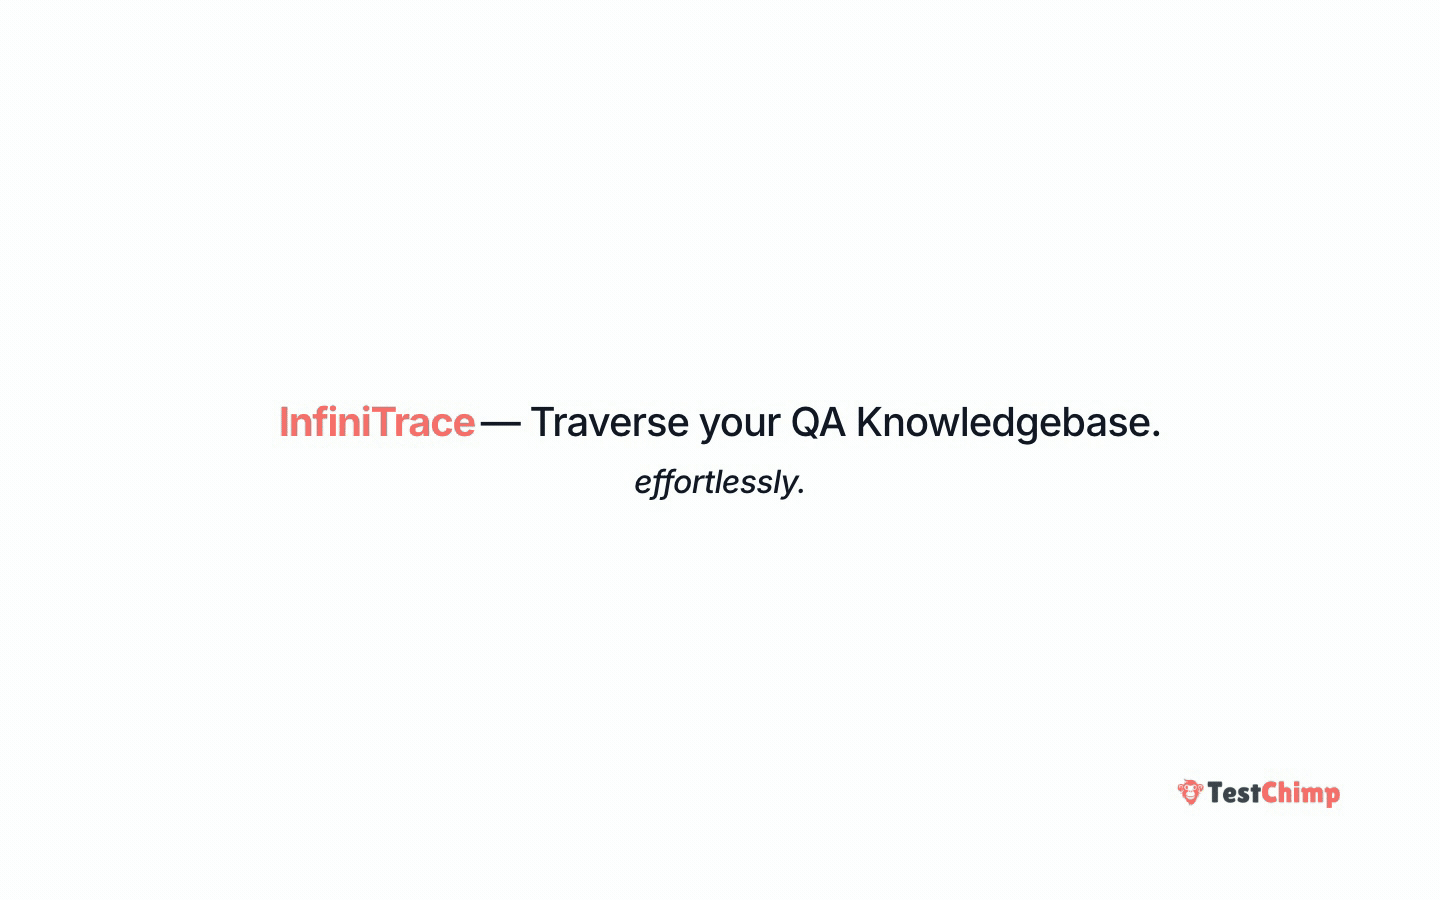
You get boards—columns—like a kanban that never pretends to be a static board. Each board is an entity type. Board N shows what’s related to the card you selected on board N−1.

  1. Choose where to start — Story, Scenario, Test, Issue, Event, Release, …
  2. Select a card → it lifts; floating CTAs show related types you can fan out to
  3. The next board fills with Linked entities (structural edges)
  4. Open Non-Linked for top-N peers—often ranked by semantic proximity
  5. Keep walking. Boards grow to the right. Change a mid-chain pick and the obsolete boards fall away

Deep links encode the whole chain in the URL (?locator=), so “look at this path” is a share, not a screenshot.

Docs: InfiniTrace.


Linked vs Non-Linked is the point​

Structural links are great when they exist.

The interesting work often sits in the gap: things that should be linked, or are nearly the same idea in embedding space, but aren’t wired yet.

That’s why every follow-on board has two panes:

PaneJob
LinkedGround truth from entity links and type adapters
Non-LinkedCandidates—default sort by semantic proximity where embeddings exist

From Non-Linked you can Link (when rules allow) or Create issue—without losing the chain you were walking.

Some edges stay derived (for example TEST ↔ EVENT from RUM / SmartTest emissions). InfiniTrace shows them; it doesn’t pretend every edge is a manual click.


Why this matters for agents too​

Humans aren’t the only consumers of this graph.

The same related-entity query model is what we want agents to use via CLI / MCP later: “give me type X related to entity Y, ordered by this strategy, filtered like this, top N.” InfiniTrace is the human-shaped surface of that API.

If you’ve been following our build-in-public arc—policy-traceable workflows, TrueCoverage, plans-as-code—the theme is the same: don’t hide the structure agents need in chat history. Put it in durable, queryable form.

InfiniTrace makes that structure visible and walkable for people first.


What you can actually do with it today​

A few chains that already earn their keep:

  • Story → Scenario → Test → Execution — coverage and run health in one pass
  • Event → Test — TrueCoverage hotspots meet automation identity
  • Release / Test run → scenarios & executions — release triage without ten tabs
  • Exploration → Journey → Issues / Tests — exploratory findings with lineage

Filter, search, sort per board. View details in a read-only modal. Jump to the full entity page when you need to edit.


From scavenging to tracing​

Dashboards tell you what’s trending.

Atlas tells you where in the product structure something lives.

TrueCoverage tells you what real users do versus what tests cover.

InfiniTrace tells you how the pieces connect—and where the graph is still incomplete.

That’s the difference between staring at metrics and actually following the thread.

Go open QA Brain → InfiniTrace, pick a story or a hot event, and walk it. If the Non-Linked pane surprises you with a near-miss that should have been linked months ago… good. That’s the product working.

Full walkthrough: InfiniTrace docs.

Policy-Traceable Workflows: Close the Loop on Agent Outcomes

· 7 min read
Nuwan Samarasekera
Founder & CEO, TestChimp

TL;DR: Loops are winning in prompting because you can trace outcome quality back to the prompt and improve it. We’ve deconstructed agentic SDLC work into <workflow> + <task description> + <behaviour guidance>, catalogued ~12 modular QA workflows (plus composites like run-qa and upkeep), and put the behaviour piece in version-controlled policies in your repo. Every workflow execution records policy file · version · git SHA—so outcome data can feed back into the policy. From ad-hoc gut-feel prompting → traceable, structured, modular workflows.

From ad-hoc prompting to policy-traceable workflows


Loops win when you can close them​

Loops are all the rage in prompting today—and rightly so.

If you can trace the quality of an agent’s work back to the prompt, you get a feedback loop.

Better prompts → better outcomes.

We’ve been cooking something along those lines. But instead of treating every agent invocation as a raw blob of prompt text, we deconstructed agentic interactions a bit first.


Most agent work is three parts​

Look carefully at how agents are actually used in the SDLC. Most interactions are of the form:

<workflow> + <task description> + <behaviour guidance>

What’s interesting is that the first part has a surprisingly small vocabulary.

Author Story. Implement Task. Write Tests. Fix Issue. Fix Test Failure…

For QA, we found these distill into around 12 core workflows—plus a couple of composites for shorthand (run-qa, upkeep). The Workflows catalog is that vocabulary: modular playbooks the skill and the platform share.

From there, outcome quality mostly depends on two things:

LeverWhat it isWhat goes wrong when it’s weak
Task descriptionThe what—story, bug, failing batch, scopeVague inputs → confident wrong work
Behavioural guidanceThe how—conventions, env strategy, quality bar, team “tricks”Same task, wildly different agent behaviour per person / day

Today, both still happen ad-hoc—with gut feel. Someone pastes a long prompt, tweaks a line that “felt” important last time, and hopes the next run is better. There is no durable artifact to improve. There is no evidence trail tying this outcome to that guidance.


We already hardened the task side​

We’ve been attacking the task-description lever for a while:

  • DeFOSPAM requirement quality checks — score and fix ambiguous specs before agents spend tokens implementing or automating them
  • Rich context for failures — fix-test-execution and related workflows pull execution detail instead of “tests are red, please fix”
  • Test Planning as Code — stories and scenarios as markdown in Git, so the task itself is structured and agent-readable

That closes one half of the loop: better inputs into the agent.

The other half—how the agent should approach the work for your team—was still mostly vibes in a system prompt.


Introducing policy-traceable workflows​

Today we’re making that second lever first-class: policy-traceable workflows.

Each catalog workflow is backed by an optional policy—a Markdown file that defines how the agent should approach the task for your project. Policies are not secret sauce buried in a chat window. They live in your repository:

plans/knowledge/policies/*.policy.md

Version-controlled. Reviewable in PRs. Shared team-wide. Same files local /testchimp runs and Automations use.

---
workflow-id: implement
version: 1.2.0
---

Playbooks stay generic (the battle-tested skill steps). Policies hold the project choices: scoping rules, environment strategy, which composite subflows to run or skip, quality bars, exclusions, domain quirks.

Author or refresh them with /testchimp create policy <workflow-id>. Bump version whenever guidance changes—that version is what makes the loop measurable.

Full model: Workflows · Policies.


Trace every execution to policy · version · SHA​

A policy you can’t attribute is just another prompt.

For Plan → approve → Execute runs, the agent mints a stable workflow_execution_id, then reports mutative actions with:

  • which policy file was used
  • the policy version
  • the git SHA it came from

…alongside workflow id, actor, branch, and entity identity. That lands on the Workflows execution timeline in TestChimp—not only in chat history that evaporates when the session ends.

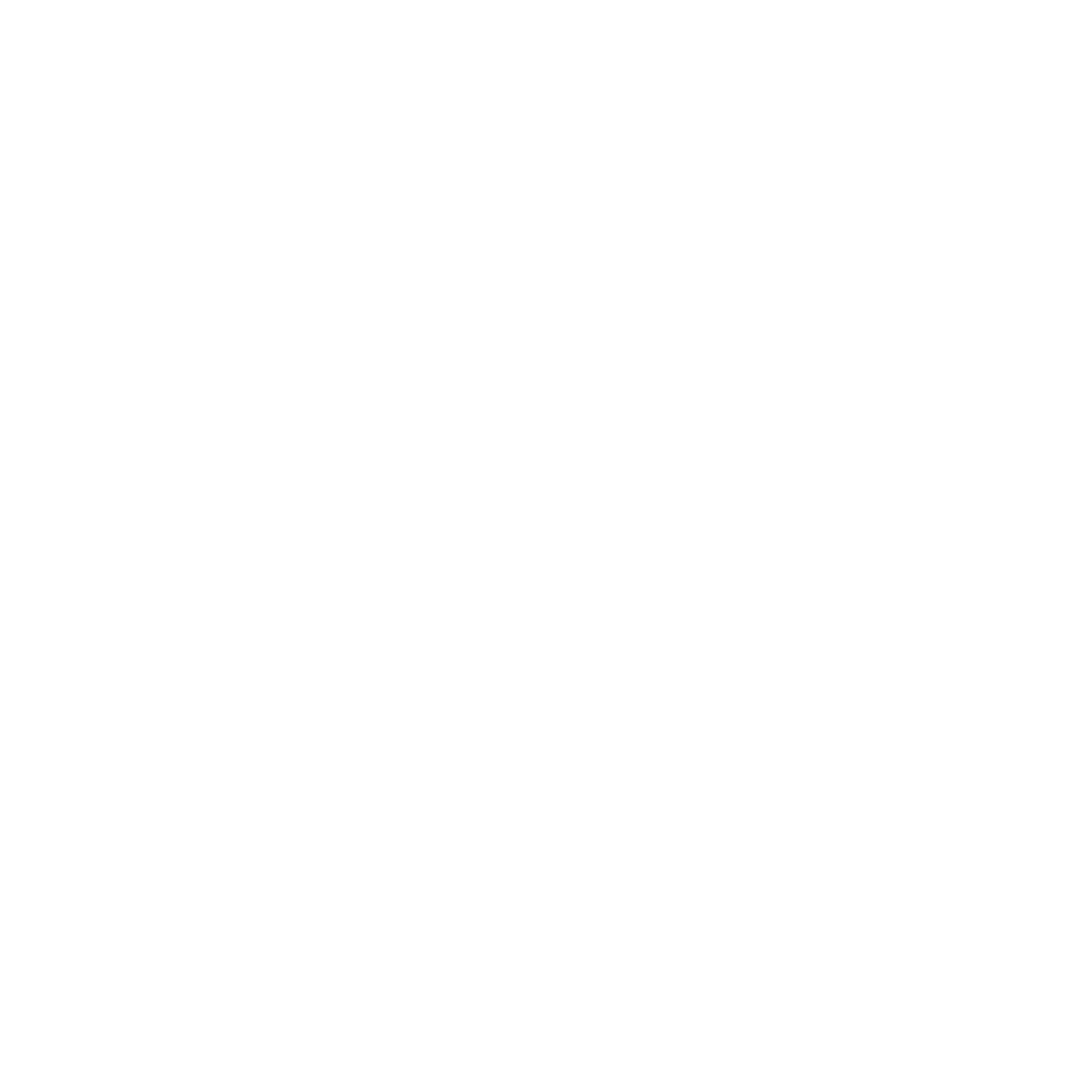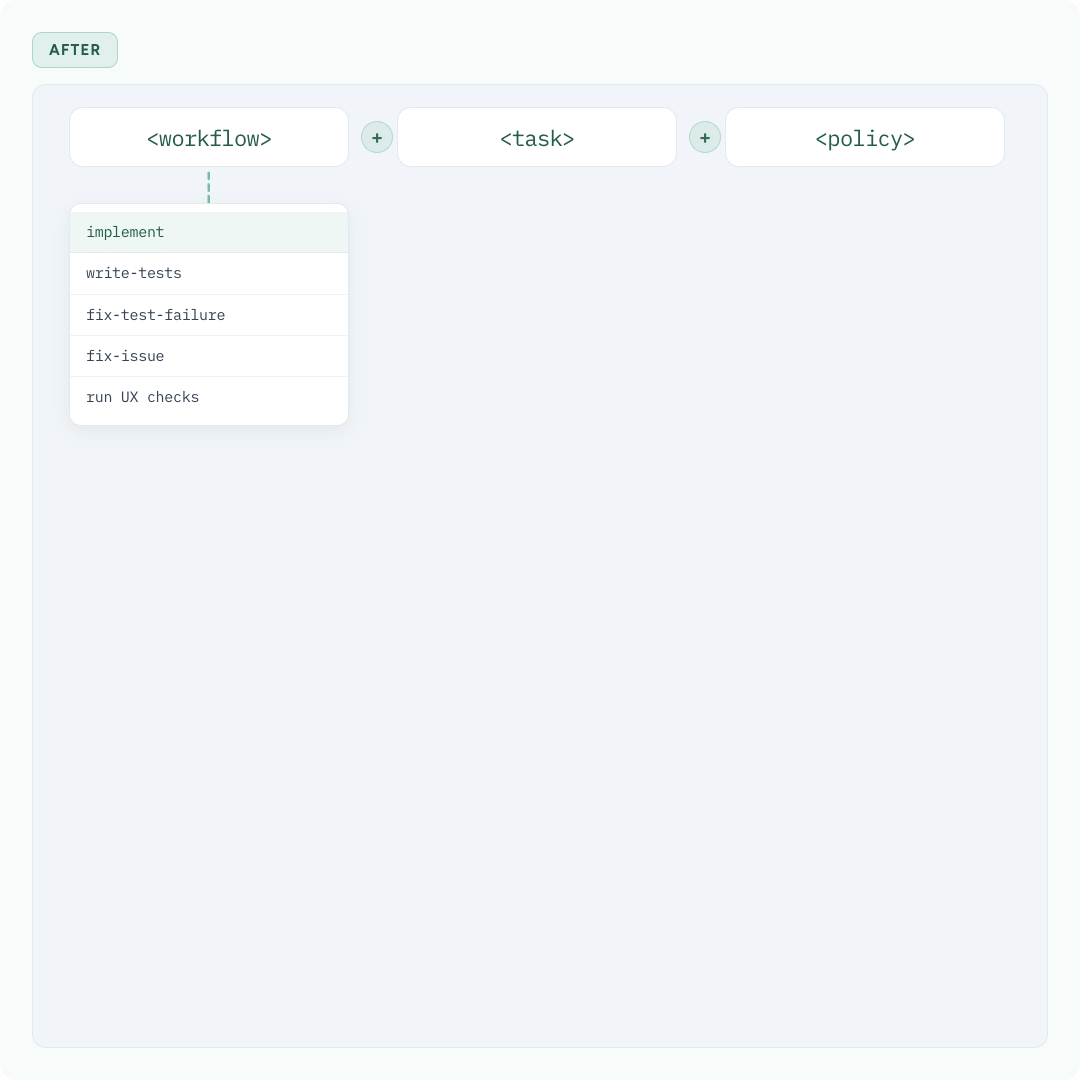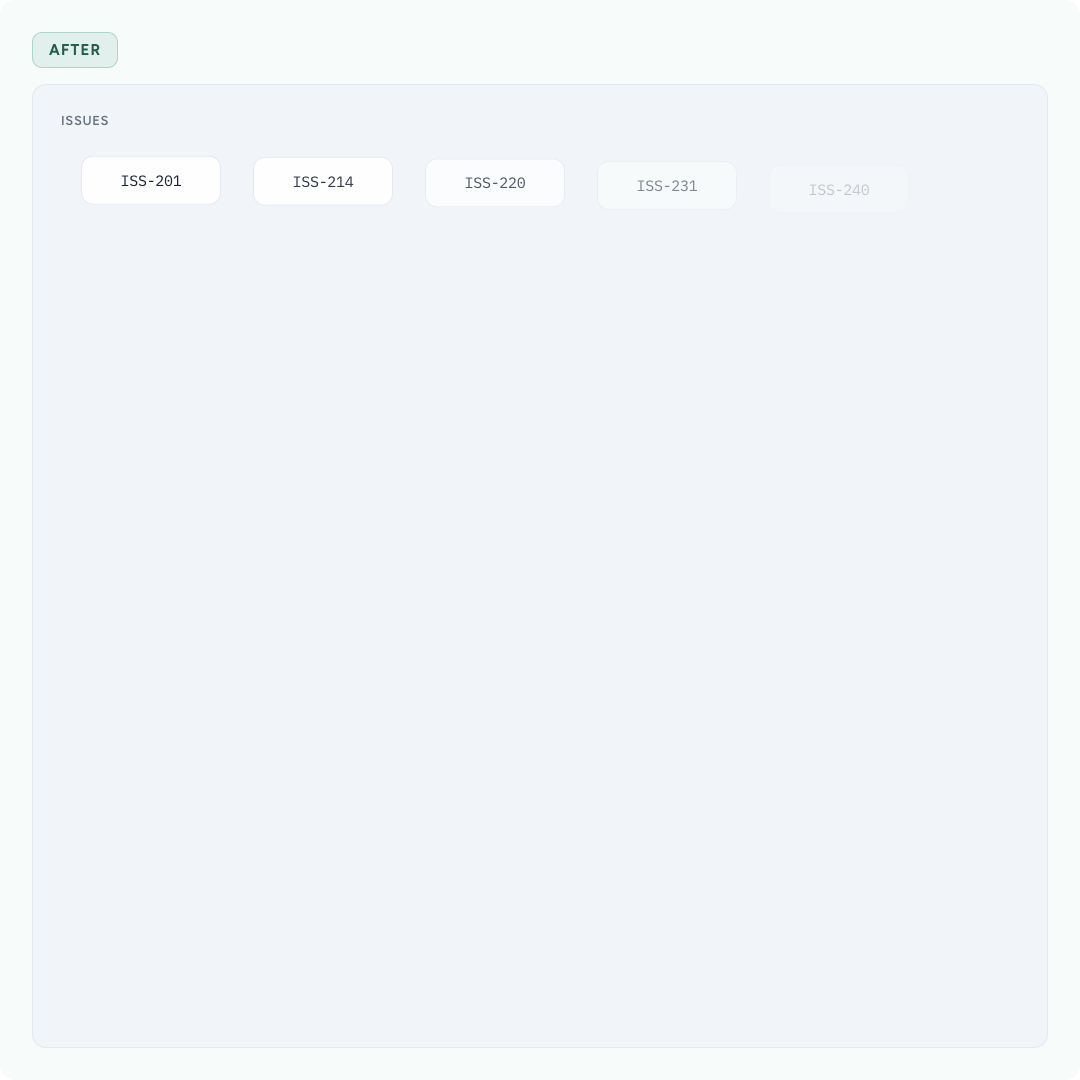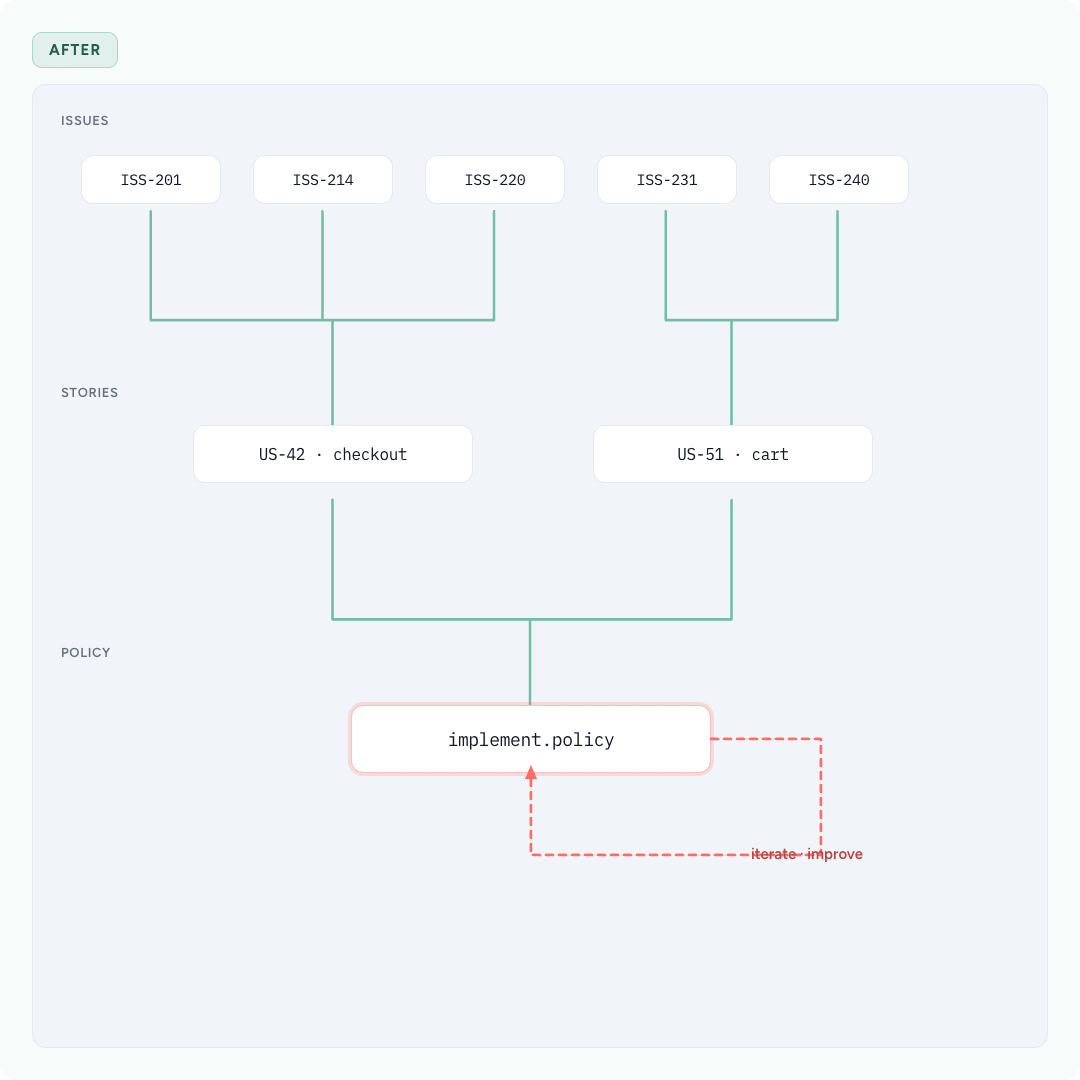
The result is data you can use to improve policies. Data you can feed to an agent alongside the existing policy—to iterate on it.

SignalWhat you might do
Stories implemented under policy v1.1 keep producing the same class of bugsPolicy is missing domain knowledge—add it, bump to v1.2
Two ExploreChimp policies, same app pathsKeep the one whose findings your team actually acts on
Smoke vs full run-qa variantsCompare outcome quality and cost without forking the skill
Flaky-fix runs under a “forbid large refactors” ruleTighten or loosen the bar with evidence, not instinct

Instead of tweaking prompts based on gut feel, you iterate on policies using evidence.


Ad-hoc prompting → modular, traceable workflows​

Put it together:

  1. Small vocabulary of workflows — implement, create-tests, fix-issue, fix-test-execution, run-explorechimp, … plus composites
  2. Context-rich tasks — governed requirements, execution detail, scoped branch diffs
  3. Versioned behavioural guidance — *.policy.md in Git
  4. Attribution on every run — policy file + version + git SHA on the execution timeline
  5. Evidence → next policy version — close the loop

That is the same philosophy as skills as SaaS distribution (the playbook travels with the agent) and boiling the QA lake (agents in a continuous feedback loop)—applied to the behaviour contract itself.

From ad-hoc prompting → to traceable, structured, modular workflows.


Frequently asked questions​

What is a workflow policy?​

A policy is a project-owned Markdown file (plans/knowledge/policies/*.policy.md) that tells the agent how to run a catalog workflow for your team—scoping, env, quality bar, composite subflows, exclusions—without rewriting the skill playbook.

How is this different from a system prompt or CLAUDE.md?​

Those are useful, but usually opaque and hard to A/B. Policies are per-workflow, semver’d, synced to the platform, and recorded on every execution with file name, version, and git SHA—so you can compare runs and improve the guidance with evidence.

Do I need a policy for every workflow?​

Defaults are seeded for common composites (run-qa, upkeep) on /testchimp init. Some workflows (notably connect-to-test-env) need an explicit policy before dependent automation stays healthy. Atomic workflows can fall back to broader instructions—but named policies are what make optimization and auditability real.

How do I try an alternate policy without changing the default?​

Keep implement.policy.md as the team default and pass a variant:

/testchimp implement US-181 --policy implement-strict.policy.md

Same playbook, different behavioural contract. Compare outcomes on the execution timeline.

Where do I see policy traceability?​

Executions → Workflow Executions (and the Workflows UI timeline). After mutative actions, reported runs show the policy file and version used for that execution.


Try it​

  1. Install the TestChimp skill and map plans/tests in Git
  2. Run /testchimp init (or author policies with /testchimp create policy <id>)
  3. Open plans/knowledge/policies/*.policy.md, encode one team convention, bump version
  4. Run a workflow (/testchimp implement …, /testchimp run QA, …)
  5. Check Workflow Executions for policy file · version · SHA—then improve the policy from what you see

Start here:

Better policies → better outcomes. Now you can prove which version got you there.


Further reading​

TestChimp

Related posts

Concepts

Put QA on Auto-Pilot with Workflow Automations

· 8 min read
Nuwan Samarasekera
Founder & CEO, TestChimp

TL;DR: We've shipped Automations in TestChimp—event-driven runs of the same catalog workflows you already invoke with /testchimp. When an issue is created, a story moves to ready, a CI batch fails, or a release lifecycle status changes, TestChimp can hand the work to a cloud agent—today via ChimpHands (recommended), a labelled GitHub Issue, or a webhook. Aggregation collapses noisy bursts; optional human gates keep high-blast-radius runs under review. Local agents stay for interactive work. Automations cover the complementary case: the platform watches, then starts the agent for you.

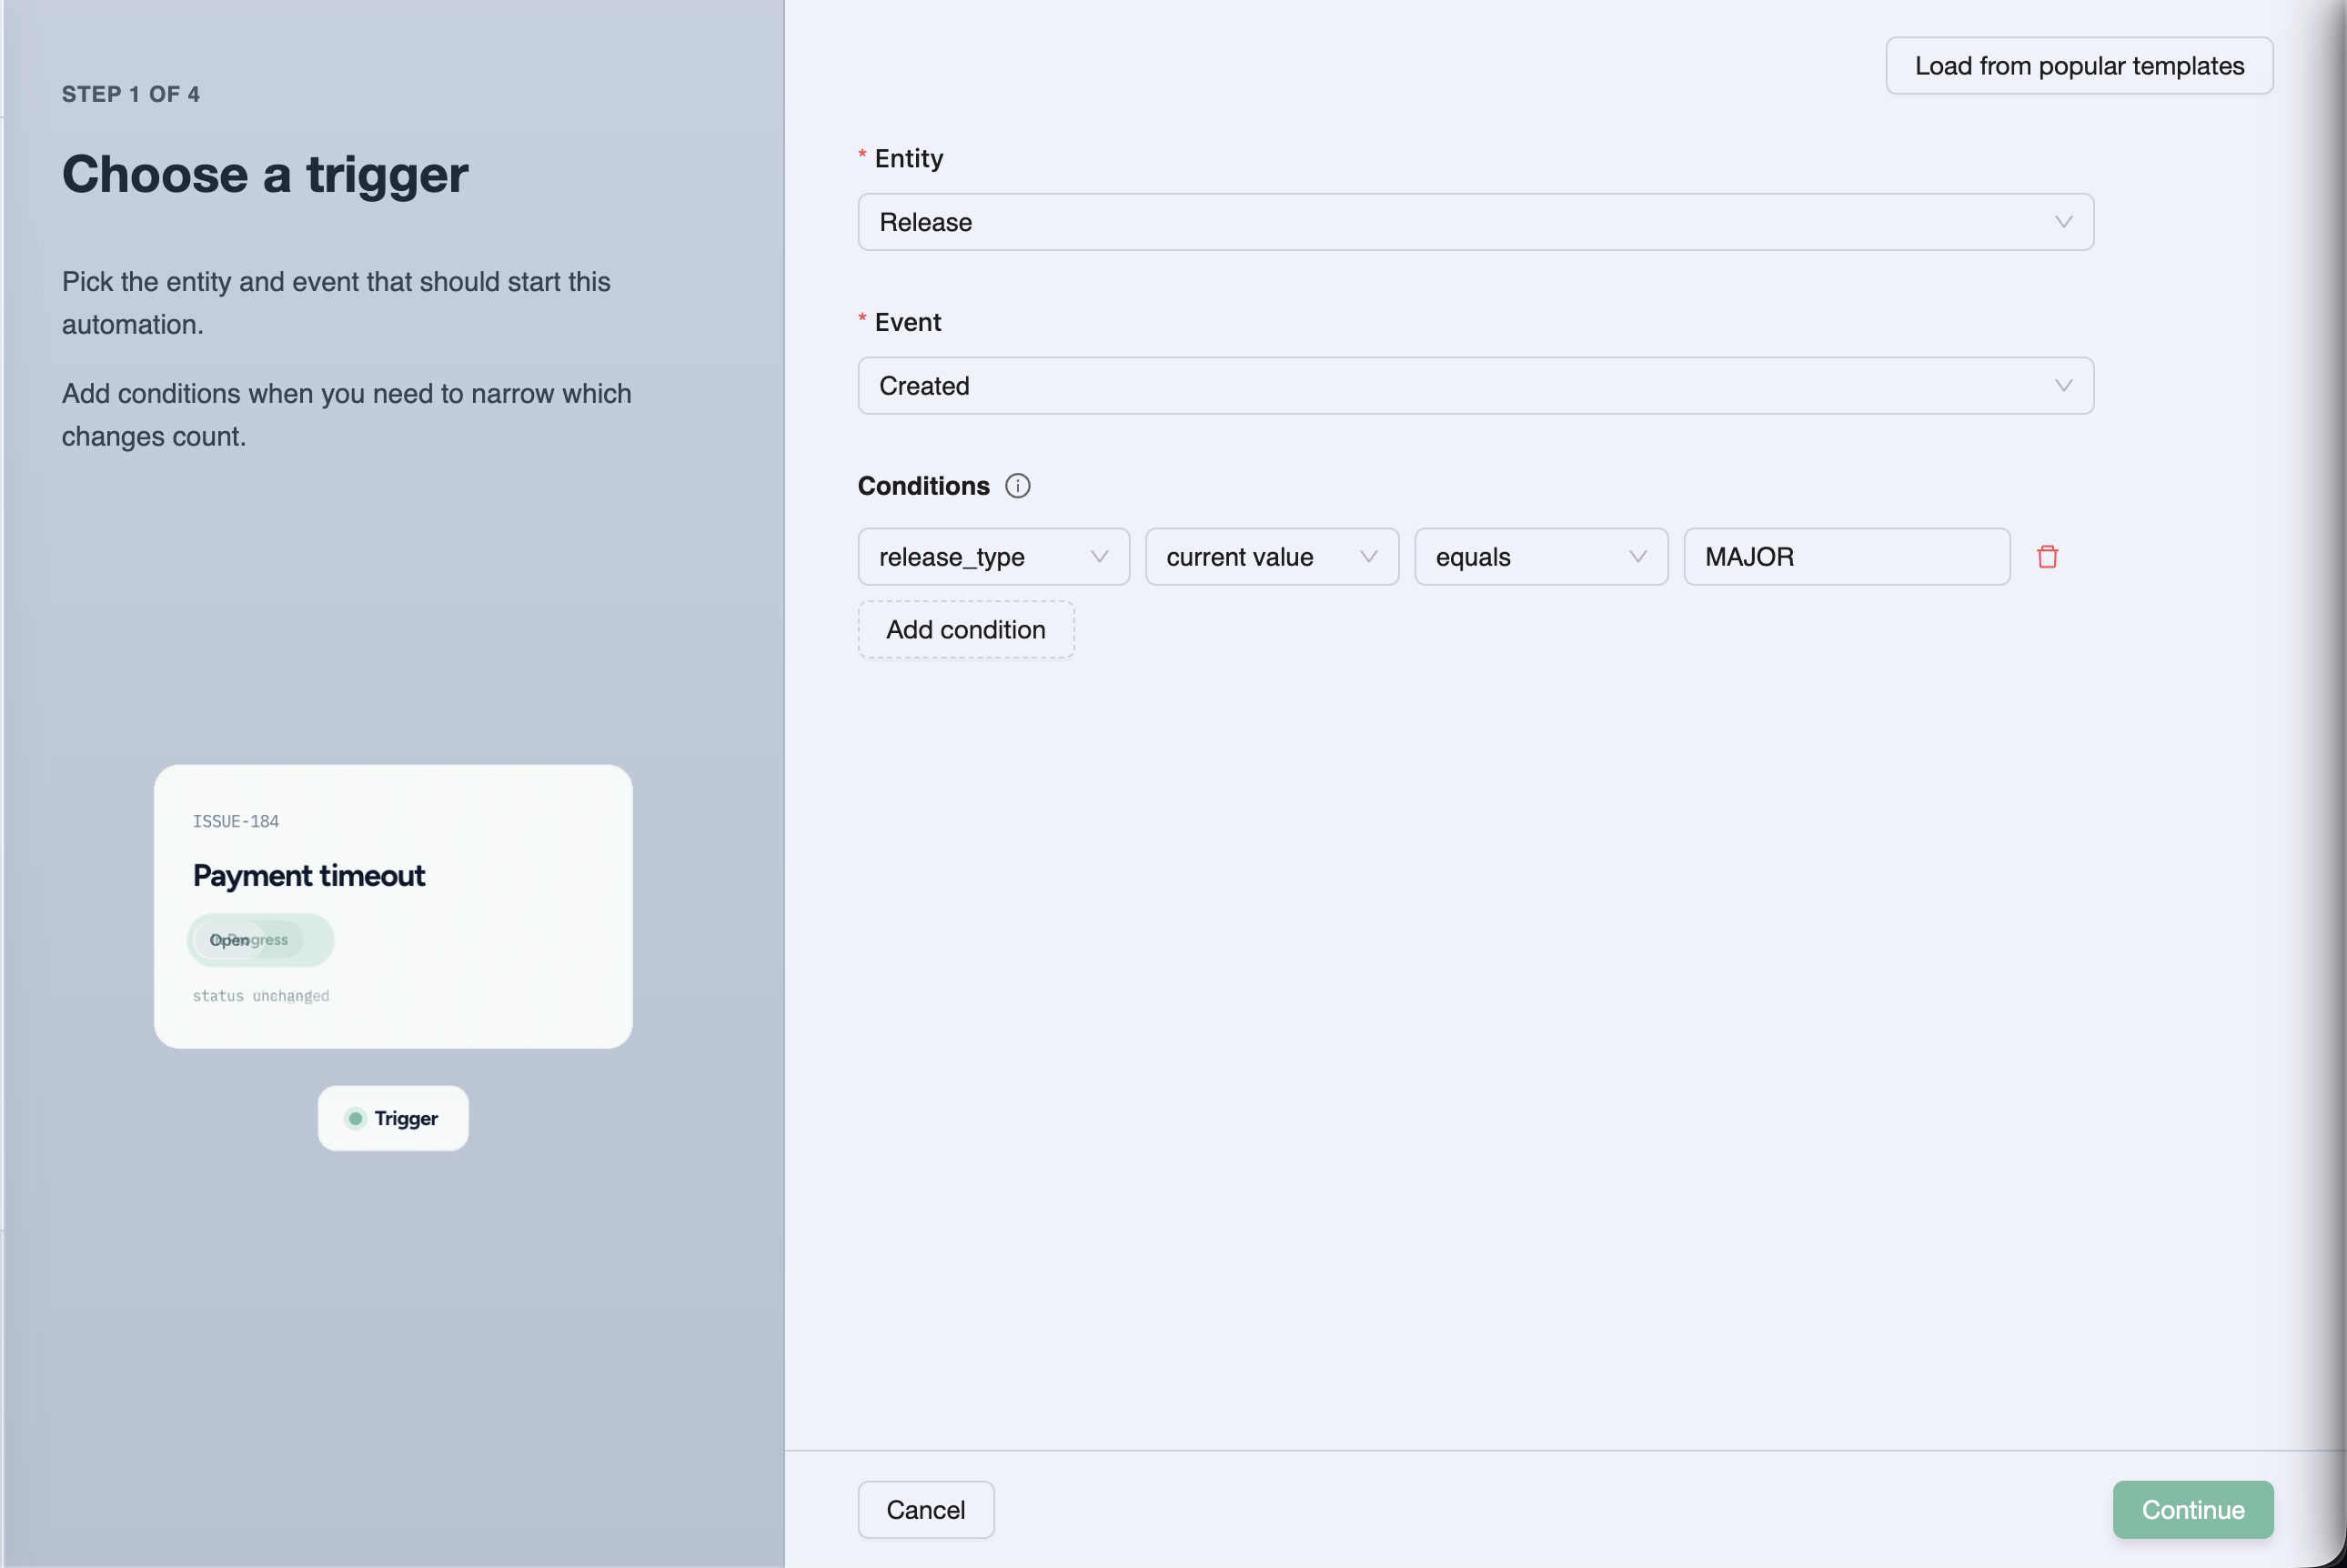
Configure an automation trigger — entity, event, and conditions


The prompt-pasting tax​

If you've been living in the agentic QA loop, you already know the playbooks:

/testchimp fix issue BUG-1042
/testchimp implement US-181
/testchimp fix test execution …
/testchimp run QA

That works. It also creates a new bottleneck: someone has to notice the event and paste the prompt.

Failure modeWhat actually happens
LatencyHigh-severity bug sits until a human opens the IDE
InconsistencyDifferent people phrase the same job differently
Missed signalsFailed CI batch, ready story, release → Ready—none of them auto-start work
No audit trailChat history ≠ a tracked workflow execution with status and policy version
Noisy burstsTen related failures → ten agent sessions unless someone batches by hand

Agents compressed execution. They did not invent routing. Automations are that routing layer—on the same workflows, policies, and workflow-execution-id traceability you already use.

Full product docs: Automations.


What is a TestChimp automation?​

An automation is three parts:

Trigger + Action + Config

PartAnswersExamples
TriggerWhen?Entity (issue, story, scenario, test execution, batch, release) + event + optional AND conditions
ActionWhat?Execute a catalog workflow with a task template, optional policy, and invocation strategy
ConfigHow loudly / how carefully?Aggregation (Immediate / Buffered / Windowed) + optional human approval before invoke and/or before plan execute

Policies stay *.policy.md in Git. Automations optionally attach them—the same files local /testchimp runs use. Workflows still define how the agent works. Automations define when that work starts and how the cloud agent is reached.

Project event → matching automation → aggregation window
↓
workflow execution queued
↓
(optional) human approve invoke / plan
↓
ChimpHands on CI or labelled GitHub Issue or webhook
↓
/testchimp <workflow> … --workflow-execution-id …

Ways to reach a cloud agent​

Configure once under Project Settings → Automations (and ChimpHands setup for the native path), then pick a strategy per automation.

TestChimp dispatches your repo's chimphands.yml GitHub Actions workflow with the rendered /testchimp … prompt. The agent runs on your CI with full checkout context, streams progress to the ChimpHands UI, and opens a PR when done.

One-click setup: GitHub App + workflow file + TESTCHIMP_API_KEY secret. See ChimpHands and Meet ChimpHands.

Via GitHub Issue (bring-your-own agent)​

TestChimp opens an issue on your mapped repo. Body = the full /testchimp … prompt (plus the workflow execution id). Labels always include testchimp, plus any extras you configure.

Point Copilot coding agent, Codex, Cursor Cloud, or your own runner at those labels. The agent checks out the repo, runs the prompt with the TestChimp skill + MCP, and reports back—so Executions → Workflow Executions stays current.

ChimpHandsVia GitHub Issue
Who starts the agentTestChimp (GitHub Actions dispatch)Your label-watching agent
NeedsGitHub App + ChimpHands workflow + API key secretTestChimp GitHub App + repo + BYO agent wiring
Continuation (plan → execute)Same session / re-dispatchComment on the same issue
FitDefault QA orchestration on your CICustom agent stacks you already operate

Deep dive: Cloud agents for automations.

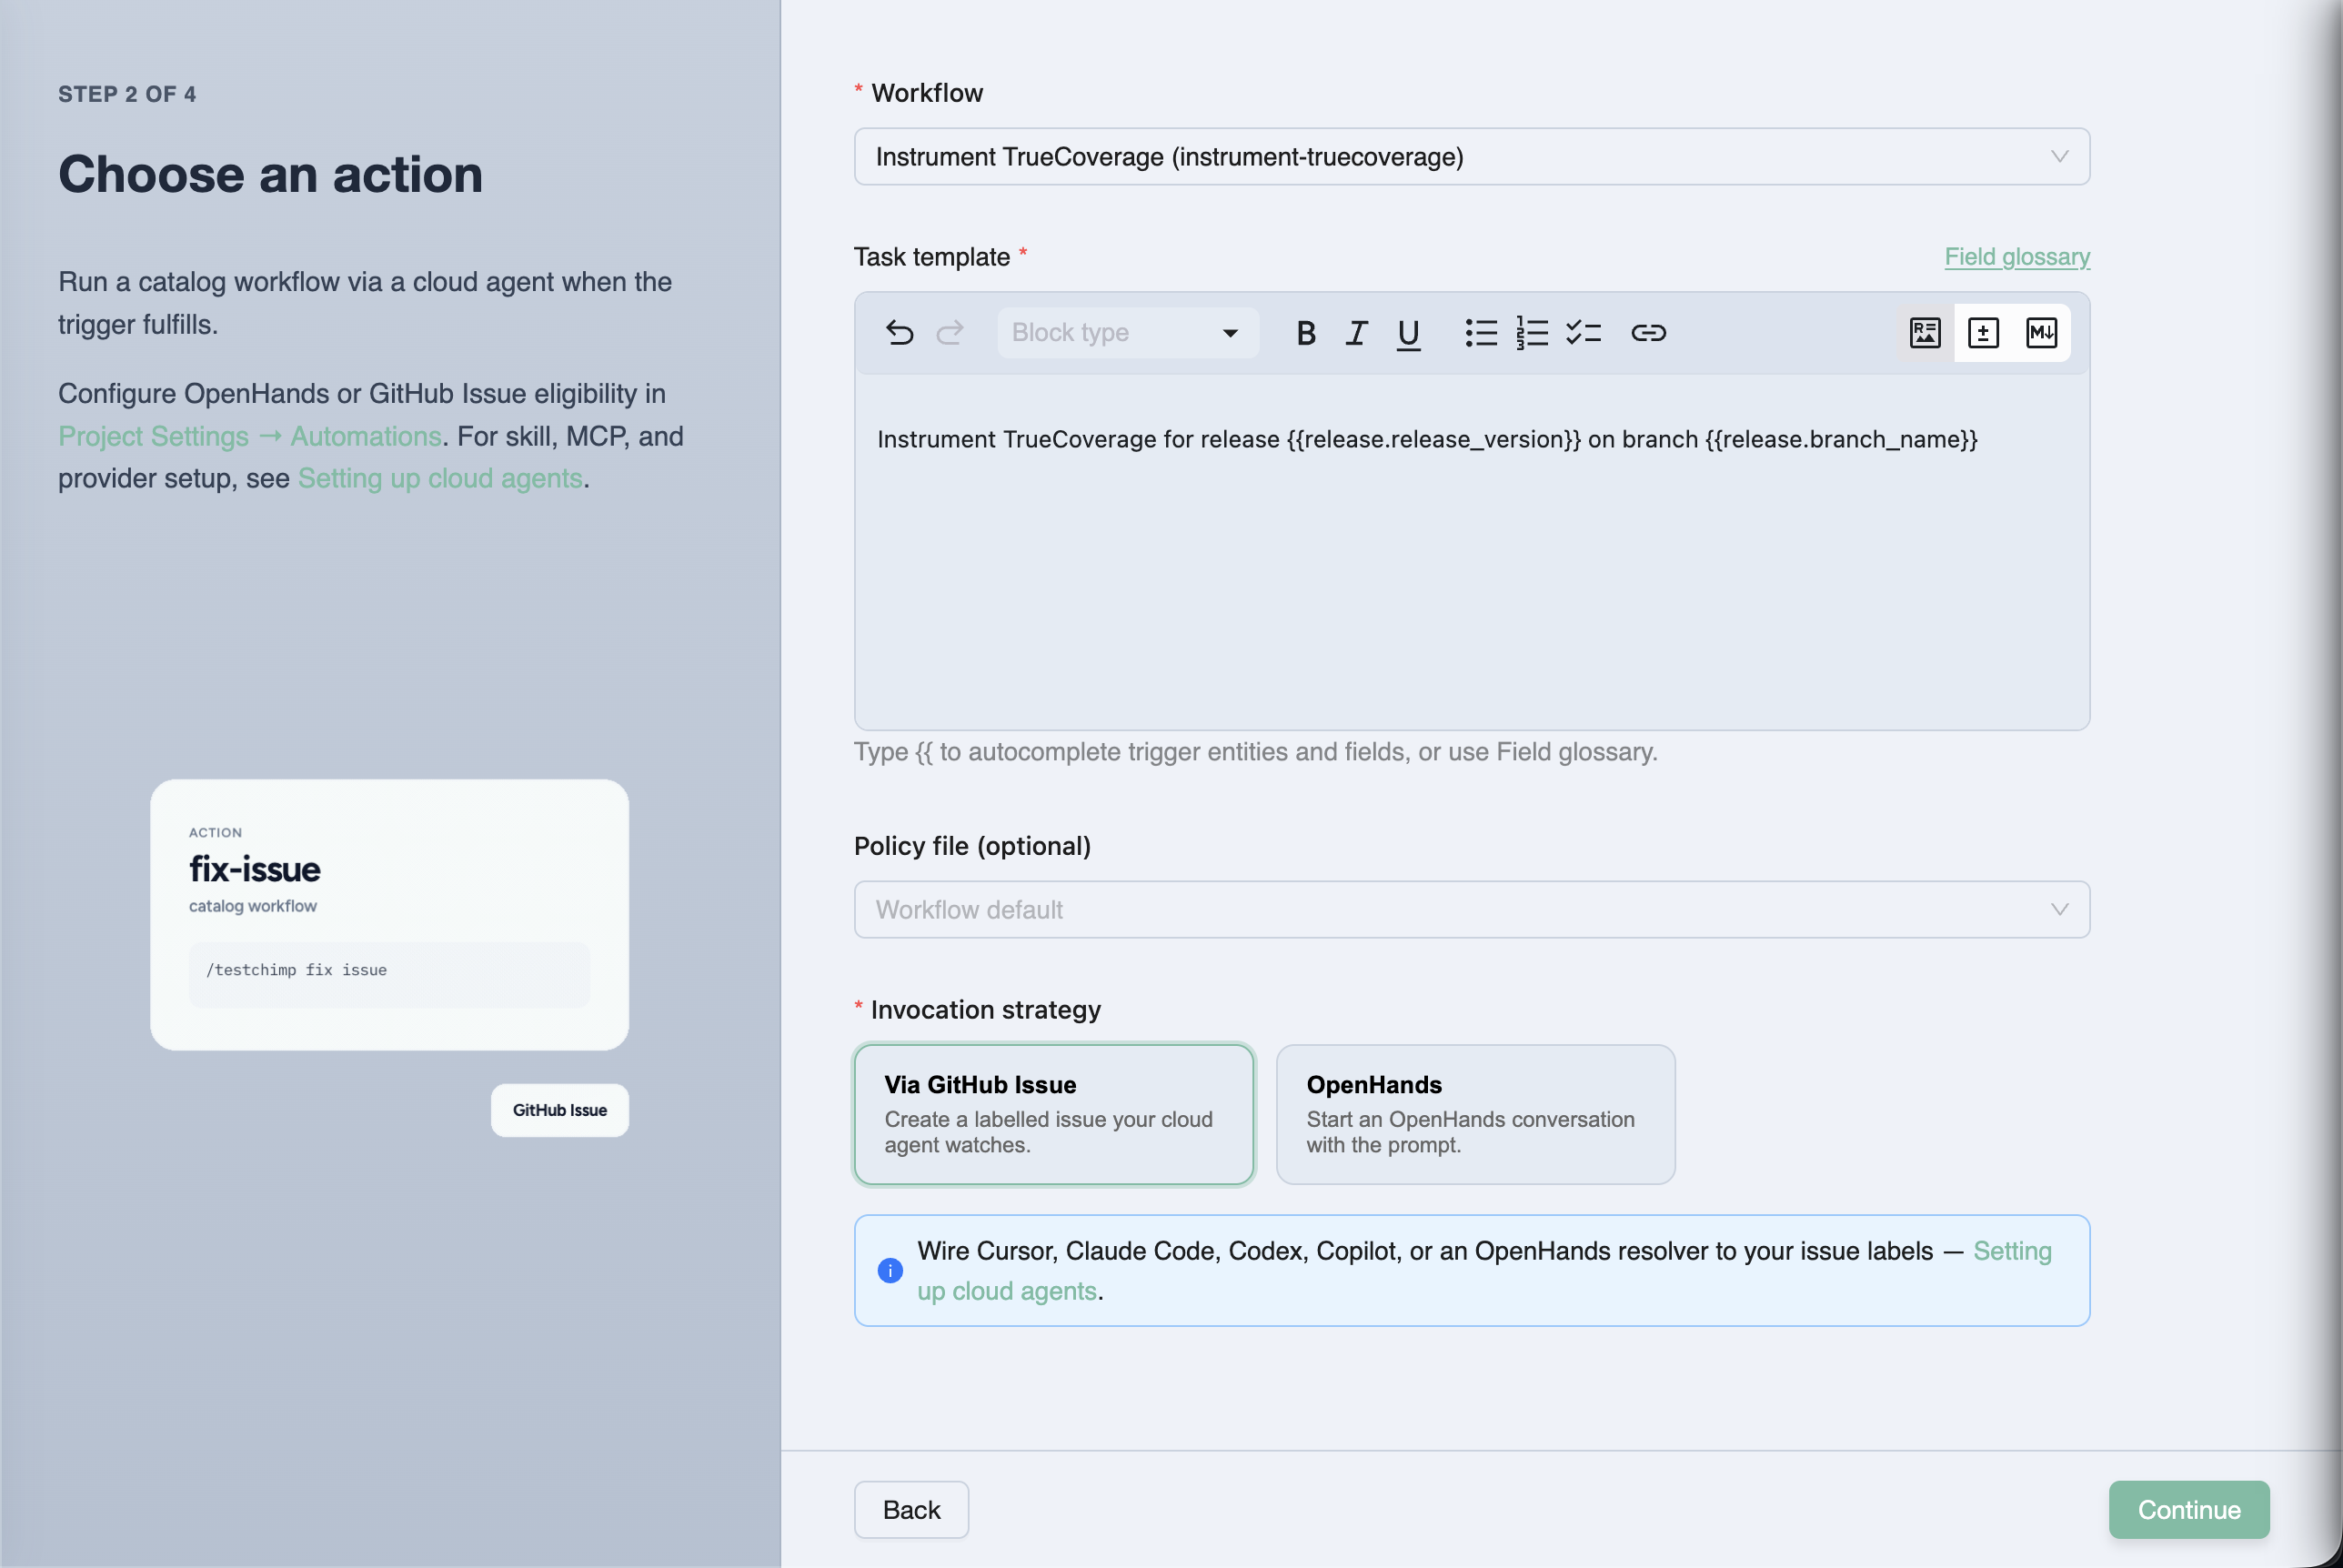
Configure the automation action — workflow, task template, policy, invocation strategy


Aggregation and human gates (because autonomy without brakes is chaos)​

Matching events should not always mean "spawn an agent immediately."

PolicyBehaviour
ImmediateEvery match fulfills (still subject to the project hourly cap)
Buffered (default)Wait for a quiet period (≥ 5 minutes), bounded by max window / max event count
WindowedFulfill on fixed hour boundaries—digest style

Default rate limit: 5 cloud agent invocations per hour per project (shared). Over-cap runs stay Queued—not dropped.

Two independent human gates (off by default):

  1. Approve before invoke — review the rendered task before the cloud agent starts
  2. Approve before plan execute — agent plans first; you approve before execute

Pending work surfaces in Executions → Workflow Executions. You can also copy the prompt and run it locally—the workflow-execution-id keeps the timeline accurate either way.

Mechanics: How automations work.


Recipes teams actually want​

SignalWorkflowNotes
High-severity issue created (not ExploreChimp noise)fix-issueImmediate or short buffer; start with invoke approval
Story / scenario → readyimplementBuffered; prefer plan-execute approval
Automation batch status → failedfix-test-execution / upkeepBuffered so one CI push → one agent run
Release → Readyrun-qa / run-release-checkImmediate; gate the composite
Steady drip of ready workupkeepWindowed hourly/daily digest

Task templates use {{issue.id}}, {{story.title}}, {{batch.failed_count}}, {{project.repo_url}}, and friends—with autocomplete in the wizard.

More starters: Typical automation setups.


Why this matters in the agentic era​

We already argued that skills are SaaS distribution—the playbook travels with the agent. We argued that requirements must be governed before agents spend tokens. We argued that release governance is the ship decision, not a spreadsheet.

Automations close another gap: intent without attendance.

Without them, QA-on-autopilot still needs a human dispatcher. With them, the same /testchimp catalog becomes a control plane: events in → policy-backed workflow executions out → auditable status in the product. Local Claude / Cursor for interactive loops. ChimpHands and other cloud agents for the overnight and the "while you were in standup" cases.

That is how you boil the lake without standing next to the kettle (boiling the QA lake).


Frequently asked questions​

What are TestChimp Automations?​

Automations are event-driven rules that run TestChimp catalog workflows via a cloud agent when something changes in your project—issues, stories, scenarios, test executions, CI batches, or releases—optionally aggregated and gated by human approval.

How do Automations differ from Workflows?​

Workflows define how an agent should work (skill playbook + optional policy). Automations define when that work starts and which cloud invocation path to use. Both share the same execution timeline and workflow-execution-id reporting.

ChimpHands vs GitHub Issue—which should I pick?​

Use ChimpHands for the default path—native sessions on your GitHub Actions runner, platform chat, and QA-metered credits. Use GitHub Issue when you must keep an external label-watching agent (Copilot, Codex, custom bots) and already have the TestChimp GitHub App.

Will Automations spam my agents on every CI flake?​

Not if you configure them well. Prefer Buffered aggregation for batches, exclude ExploreChimp reporters on auto-fix rules, use conditions (status = BATCH_INVOCATION_FAILED, severity = HIGH), and keep the project hourly invocation cap. High-risk workflows should start with human gates on.

Can I still run workflows locally?​

Yes. Automations don't replace /testchimp in your IDE. From a pending execution you can also copy the prompt—including the workflow execution id—and run it with a local agent so status still updates in TestChimp.

Where do I create and monitor Automations?​

Create under Workflows → Automations (or contextual Automations CTAs on Issues, Plans, batches, releases, and workflow pages). Configure strategies and rate limits in Project Settings → Automations. Monitor and approve under Executions → Workflow Executions.


Try it​

  1. Connect GitHub and set up ChimpHands (or configure GitHub Issue / webhook under Project Settings → Automations)
  2. Open Workflows → Automations → Create Automation
  3. Pick a trigger (start from a popular condition template)
  4. Choose a workflow, task template, policy, and invocation strategy
  5. Leave Buffered aggregation on; add invoke or plan-execute approval for risky jobs
  6. Trigger a matching event—then watch Workflow Executions

Start here:

When something changes, the agent should already be working—not waiting for you to paste a prompt.


Further reading​

TestChimp

Related posts

Concepts

Release Governance: Ship When the Evidence Says So

· 10 min read
Nuwan Samarasekera
Founder & CEO, TestChimp

TL;DR: We’ve shipped release governance in TestChimp—the workflow that answers one question before you deploy: has this version been tested enough, in the right places, with evidence we can audit? A release rolls up test runs, manual session captures, CI automation batches, release checks (UX + security), and release intelligence—so product, QA, and engineering share one readiness picture. CI and agents can gate on the same data via API.

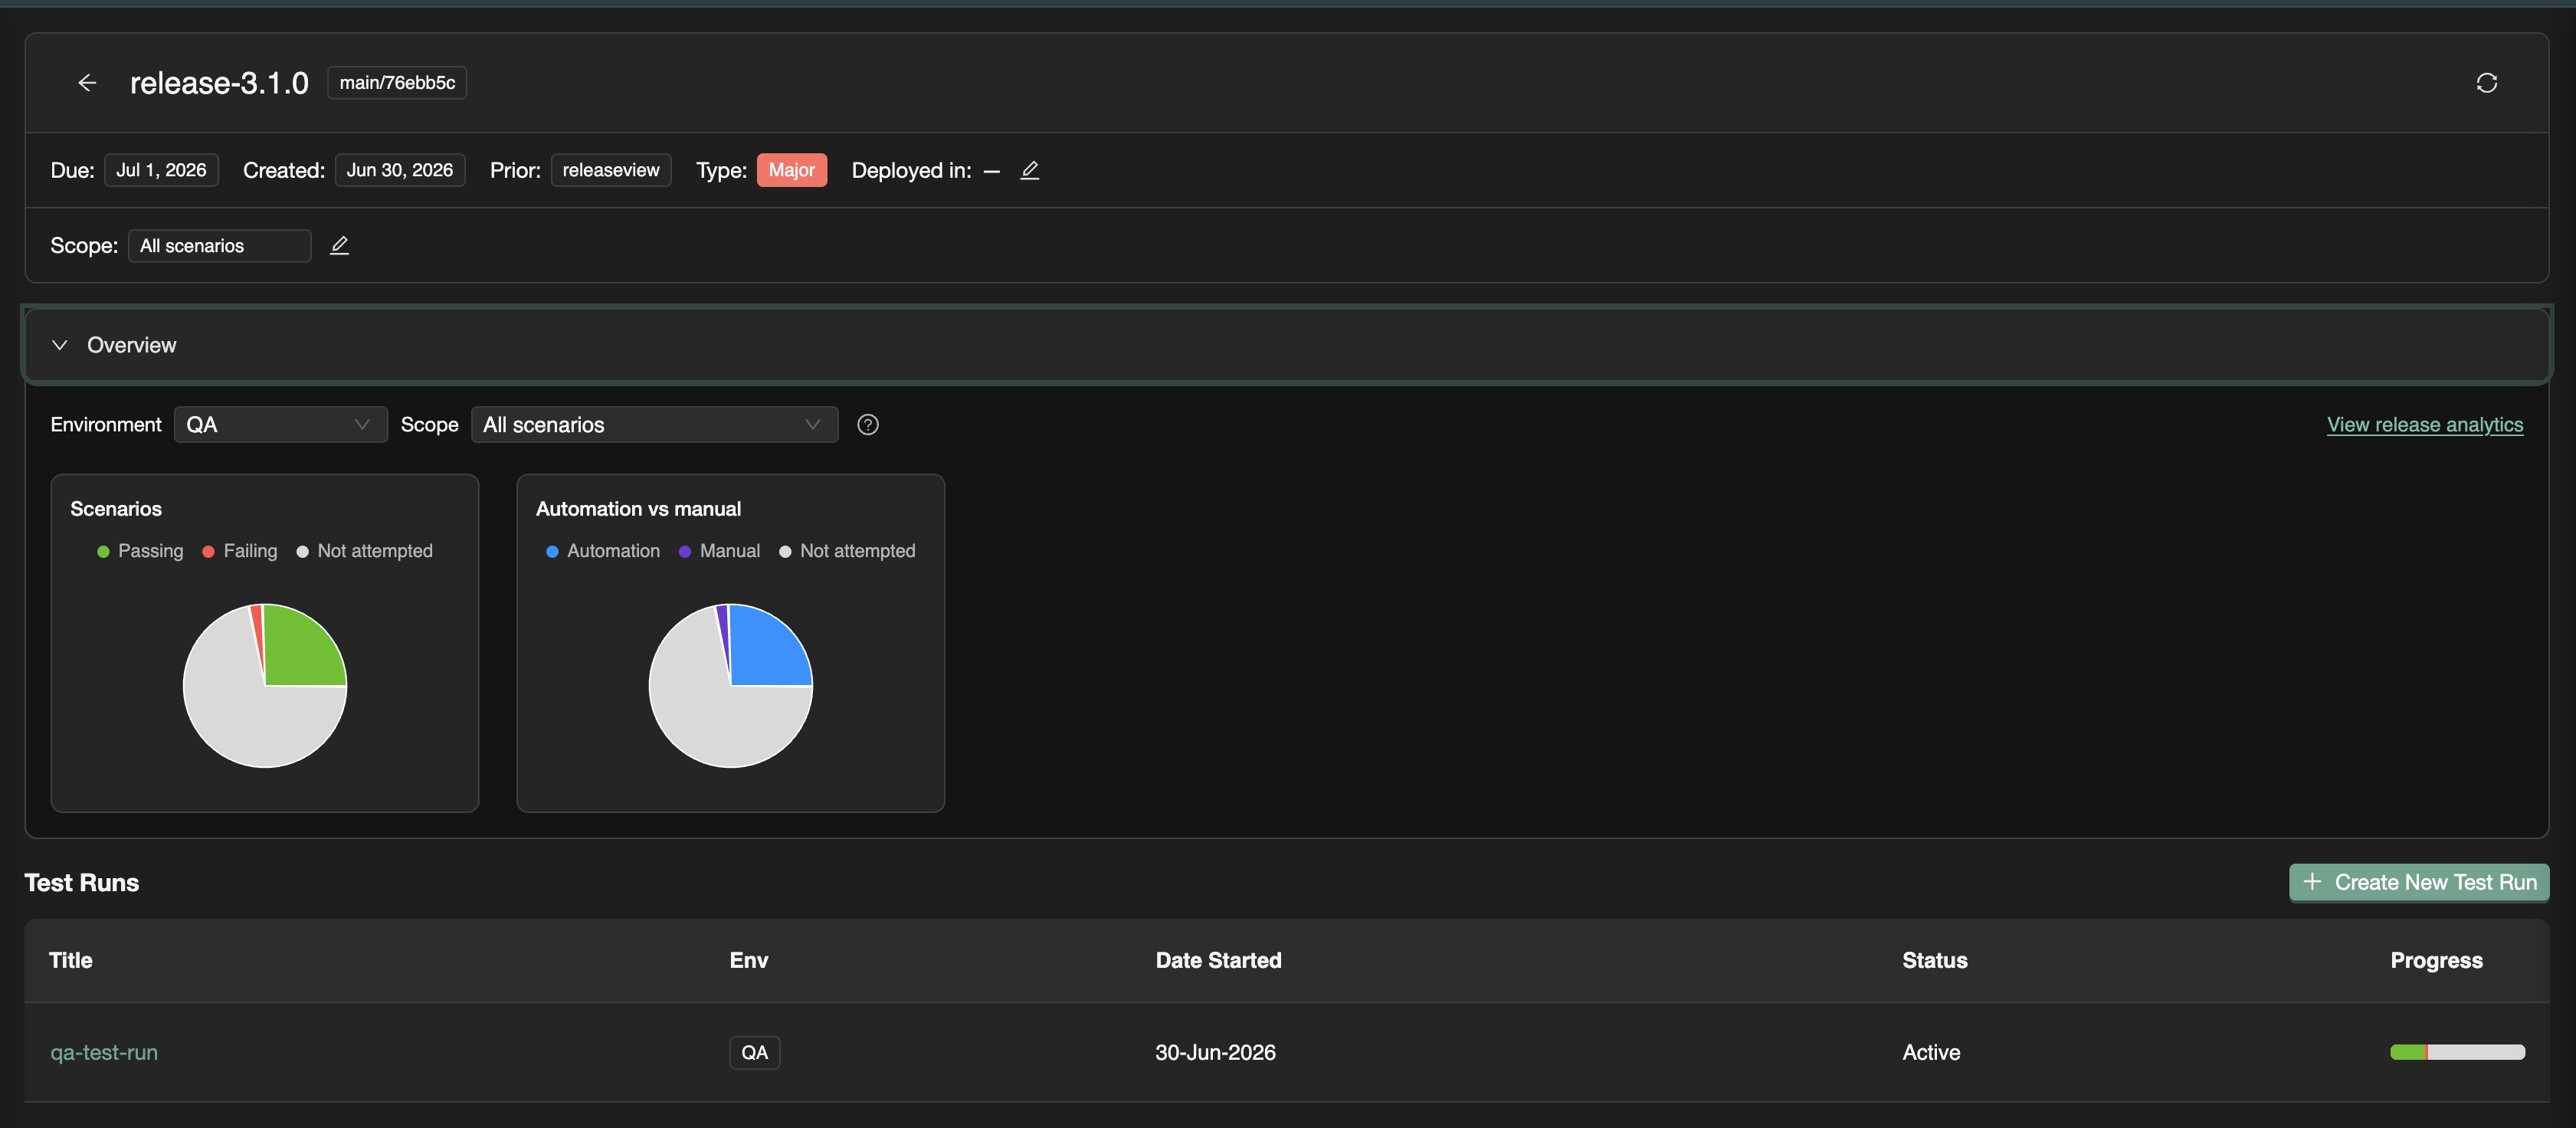
Release detail with overview charts and test runs


The release confidence problem​

Shipping fast only works when you can trust what was validated.

Most teams already run plenty of QA. What they lack is a version-level contract:

Failure modeWhat goes wrong
Scattered evidenceManual QA in Slack; CI green in another tab; no single view per version
Checkbox manual testing“Mark as passed” with no steps, screenshots, or tester identity
Automation silosPlaywright batches exist, but nobody ties them to the ship candidate
Unknown scope“We tested checkout”—but not which scenarios or requirements
Blind deploysCode merged without knowing what plans, tests, or RUM events changed

Release governance is not bureaucracy. It is the shortest path to deploy confidence when stakeholders need a shared, auditable answer—not a status emoji in #releases.


What is release governance?​

In software delivery, release governance is how a team decides a version is ready to ship: what was in scope, what was tested, what risk remains, and who can prove it.

Industry practice usually spans test planning, requirement traceability, regression campaigns (test runs), security review, and a release gate—a pass/fail policy before production. Traditional tools often split that across a TMS, CI dashboards, a security scanner tab, and a spreadsheet.

Release governance in TestChimp keeps that decision on one surface: the release—a versioned milestone (for example v2.4.0) with git commit context, focus areas from your plan, test runs, checks, and analytics.

Full walkthrough: Release Management.

Release Governance with TestChimp — video walkthrough


The TestChimp release model​

If you’ve followed us, the pieces already exist as Test Planning as Code, Test Runs, and requirement traceability. Release governance is the campaign layer that binds them to a ship candidate.

ElementPurpose
ReleaseVersion, due date, git commit SHA, prior release, deployments per environment
Focus areasOptional scope on your test plan—which story/scenario folders matter for this version
Test runsNamed validation campaigns (“Smoke on staging”, “Payment sign-off”) attached to the release
Execution evidenceManual sessions + automation batches linked to those runs
Release ChecksUX (ExploreChimp) and security scans scoped to the candidate
Release intelligenceDelta analytics, requirement coverage, ExploreChimp findings, TrueCoverage changes

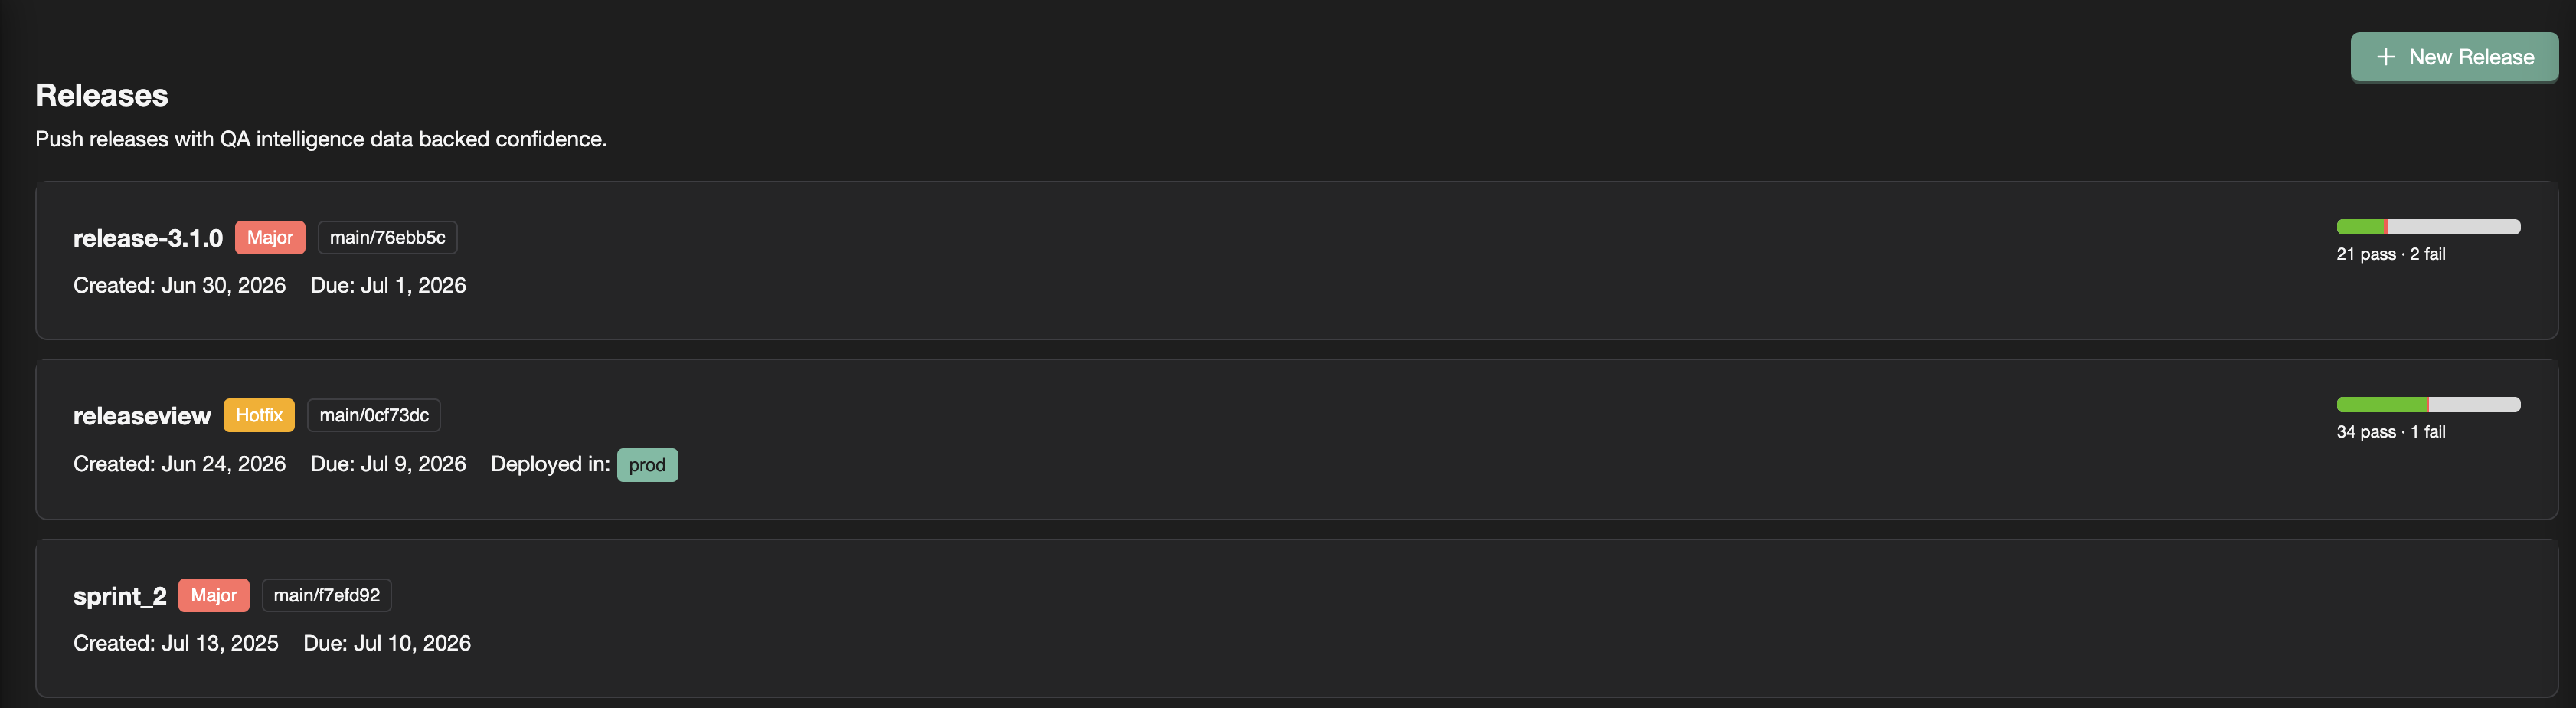
Open Releases in the sidebar → create a version → create test runs from the release viewer. Progress, checks, and analytics stay anchored to that label and commit range.

Releases list with progress bars


Evidence that rolls up: manual + automation​

Auditable manual testing​

Traditional TMS tools record an outcome. Release sign-off usually needs evidence.

With TestChimp, testers:

  1. Capture a session in the Chrome extension (or add a record in the test run viewer)
  2. Pick the active test run on the release
  3. Get steps, screenshots, notes, bugs, and tester identity rolled into release overview and requirement coverage

“QA said pass” becomes a reproducible session tied to the scenario and version. Details: Manual sessions to test runs.

CI that counts toward the release​

Automation batches from the Playwright reporter show up under Executions. For release work, link them to a test run—especially from the Candidate Automation Execution Batches panel (batches between prior and current release commits).

Linking answers: Does this CI run count toward our sign-off campaign? Scenario status updates in the same progress view as manual work. Guide: Linking automation batches.

One release. One progress bar. Both execution types.


Release Checks: UX and security on the ship candidate​

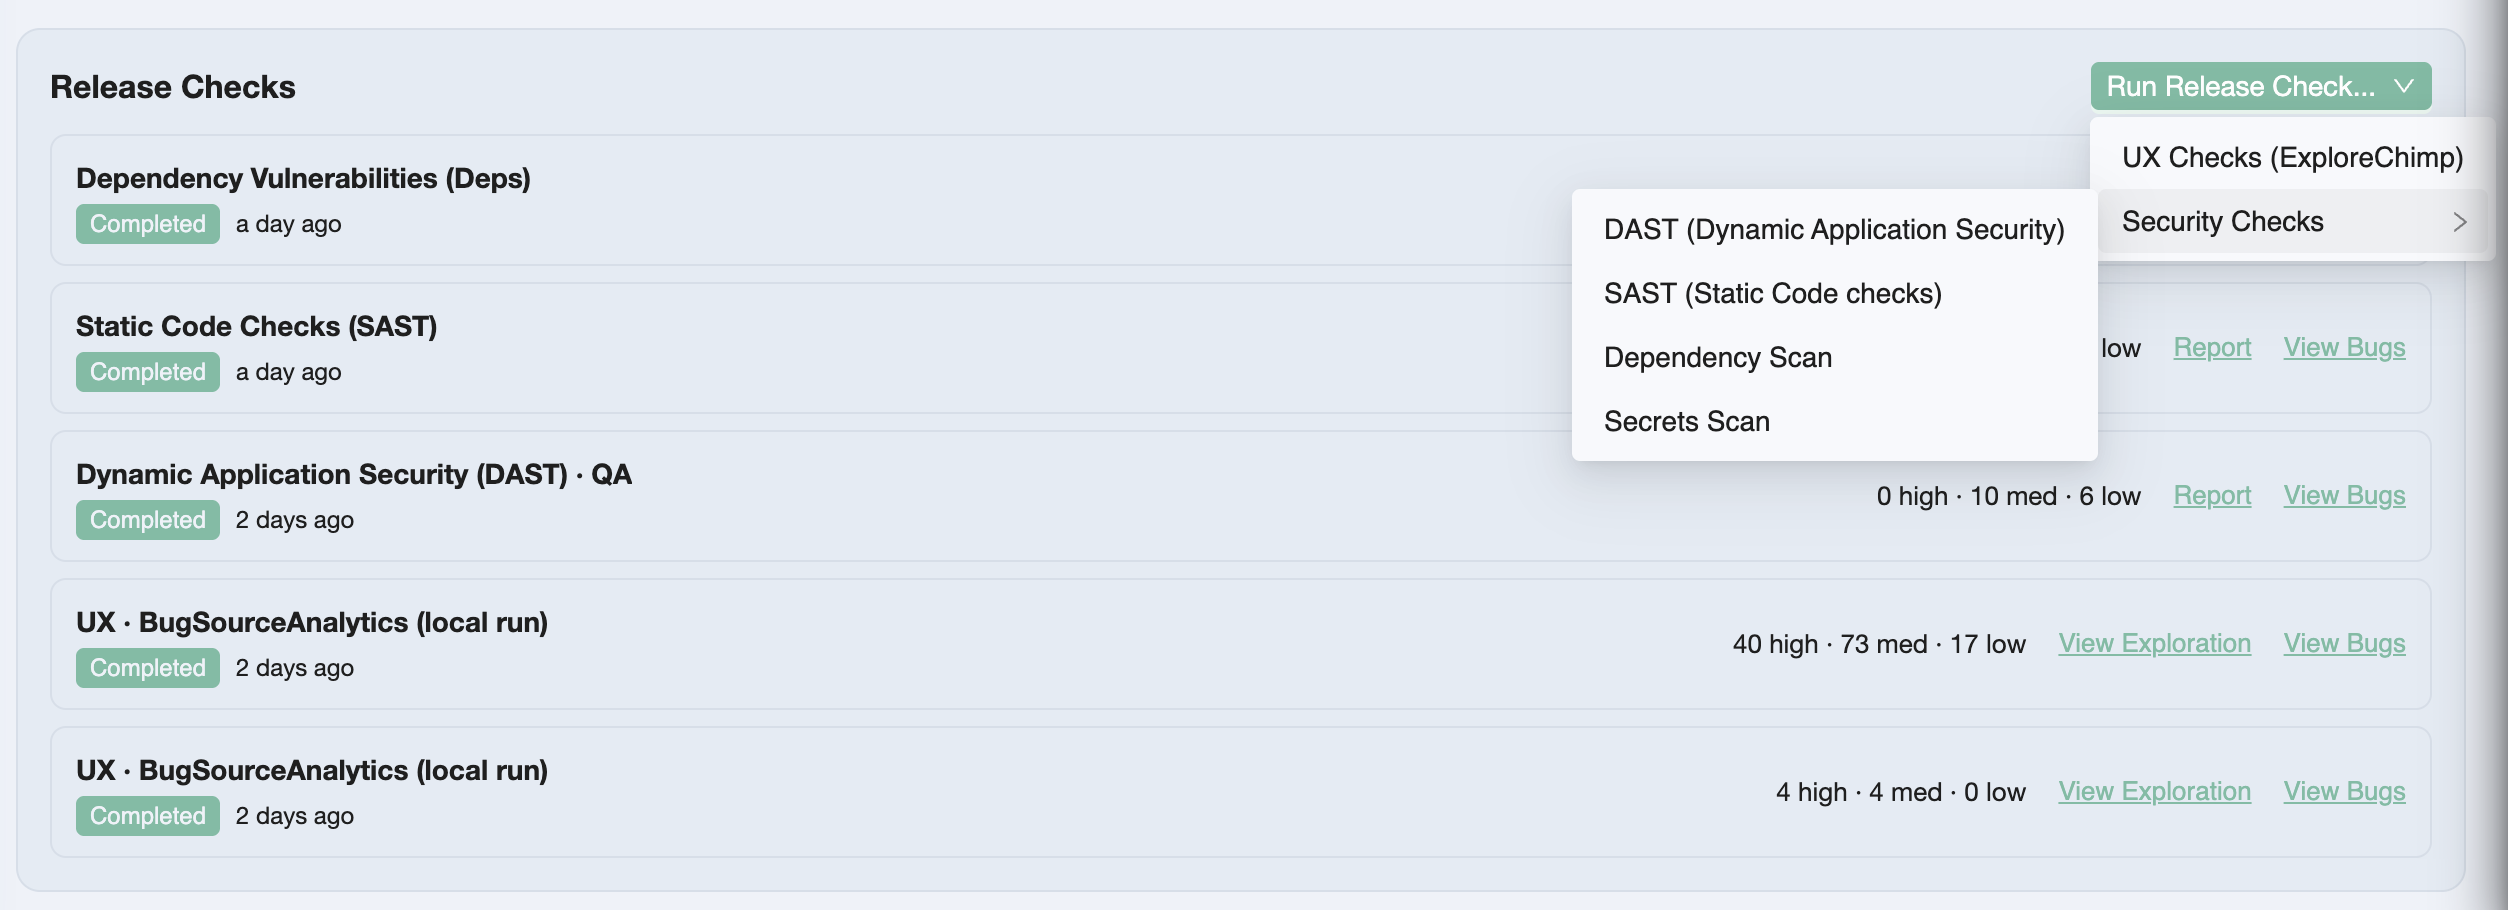
Test runs answer scenario pass/fail. Release Checks answer the adjacent ship questions—from the same release page:

QuestionCheckEngine
Did UX regress on paths this release touched?UX ChecksExploreChimp on SmartTests
Runtime web vulns on covered flows?DASTOWASP ZAP
Insecure code patterns in this range?SASTSemgrep
Secrets committed since baseline?Secrets scanGitleaks
New dependency CVEs?Dependency scanTrivy

Release Checks list on the release detail page

You queue a check from Run Release Check…, paste the /testchimp run… prompt into a TestChimp-upskilled agent, and triage Report / View Bugs beside test runs—not in a separate security silo.

Overview: Release Checks.


Release intelligence: beyond pass/fail counts​

Release intelligence connects what changed since the prior release to what was tested and what exploratory work found.

InsightWhat it shows
OverviewScenario pass / fail / not attempted; automation vs manual mix
Requirement coverageStories and scenarios mapped to linked executions for this candidate
Release delta analyticsTests, stories, scenarios added/updated/deleted + commit graph
ExploreChimp findingsExplorations, new screens/states, bugs in the commit range
TrueCoverageRUM event definitions added/updated—instrumentation drift risk

Use Overview in standups. Drill into analytics when you need requirement-level proof or scope risk (“scenarios added in delta, still not attempted”). Refresh after new commits, linked batches, or manual sessions.

Full detail: Release intelligence.


Programmatic release gating​

Governance that only lives in a UI is incomplete for agentic and CI-first teams.

get_release_details returns gate-oriented JSON for a version label: in-scope test aggregations per environment, open-issue stats, release-check summaries, and per-scenario detail. Your pipeline applies your policy—we don’t hard-code “block if any P0 failed.”

testchimp get-release-details --version '1.2.0'

Same data the release page shows—consumable by GitHub Actions, agents, or a custom quality gate. Docs: Programmatic release gating.


How this differs from a classic TMS release​

DimensionTestRail-style TMSTestChimp release governance
Plan sourceCases in a TMS databaseMarkdown stories/scenarios in Git
Manual resultPass/fail checkboxCaptured session (or detailed record) with evidence
AutomationImport / plugin / re-entryscenario annotations + batch link to test run
Security / UXSeparate toolsRelease Checks on the version
Release viewMilestone + run summaryRelease viewer + intelligence (delta, ExploreChimp, TrueCoverage)
CI gateOften custom stitchingget_release_details

We are not asking you to maintain a parallel TestRail library forever—import scenarios if you need to migrate, then keep Git as source of truth. Honest comparison: TestChimp vs TestRail.


Why this matters in the agentic era​

Agents compress authoring and execution. They do not invent a shared definition of “ready to ship.”

Without release governance, you get faster green CI and louder Slack threads—still no auditable answer for this version. With it, the same agents that run /testchimp test and /testchimp run security scan feed a release surface humans and pipelines can gate on.

Requirements quality (DeFOSPAM governance) hardens the contract upstream. Release governance hardens the ship decision downstream. Together they close the loop we care about: planned reality → tested reality → production reality (boiling the QA lake).


Frequently asked questions​

What is release governance in TestChimp?​

Release governance is TestChimp’s workflow for validating a specific application version before deploy: create a release (version + git commit + optional plan scope), attach test runs, link manual sessions and CI batches, run release checks (UX and security), review release intelligence, and optionally gate CI with get_release_details.

What is the difference between a release and a test run?​

A release is the version milestone (v2.4.0) with metadata, focus areas, checks, and rolled-up intelligence. A test run is a scoped validation campaign inside that release—selected scenario folders, collaborators, due date, and linked executions. One release typically has multiple test runs.

What are release checks?​

Release Checks are QA activities launched from the release detail page: ExploreChimp UX Checks plus DAST (ZAP), SAST (Semgrep), secrets (Gitleaks), and dependency scans (Trivy). Reports and bugs stay scoped to the ship candidate next to test runs.

How do I know when a release is ready to ship?​

Review overview metrics for the target environment, requirement coverage for focus areas, delta analytics for untested plan changes, release-check reports and bugs, and ExploreChimp / TrueCoverage warnings. When in-scope scenarios meet your bar with evidence attached, complete the test runs and deploy—or enforce the same bar in CI via the gating API.

Does TestChimp enforce a fixed release gate policy?​

No. The UI and get_release_details expose the data. Your team (or pipeline) decides thresholds—for example zero failed P0 scenarios, no open critical security issues, or required completed scans.

Do manual results need to be linked to a test run?​

For results to count in release overview and requirement coverage, link manual sessions to an active test run on that release—easiest at capture time in the Chrome extension. Unlinked sessions stay in execution history but do not roll up to release progress.


Try it​

  1. Open Releases → New Release (set version, commit SHA, prior release, focus areas)
  2. Create New Test Run from the release viewer
  3. Capture a manual session or link a Playwright batch
  4. Queue a Release Check and run it with your agent
  5. Open View release analytics—then gate CI with get-release-details when you’re ready

Start here:

Ship when the evidence says so—not when the spreadsheet says “LGTM.”


Further reading​

TestChimp

Related posts

Concepts & standards

How to Find Duplicate Tests in a Playwright Suite with a Semantic Graph

· 10 min read
Nuwan Samarasekera
Founder & CEO, TestChimp

TL;DR: When coding agents can write dozens of Playwright tests in a single session, the bottleneck shifts from authoring to governance: are the new tests distinct and useful, or just near-duplicates of what you already have? Semantic Graph is a free, open-source CLI that scans your suite, embeds each test semantically, clusters related tests, and renders an interactive graph so you—and your agent—can spot redundancy before it compounds.

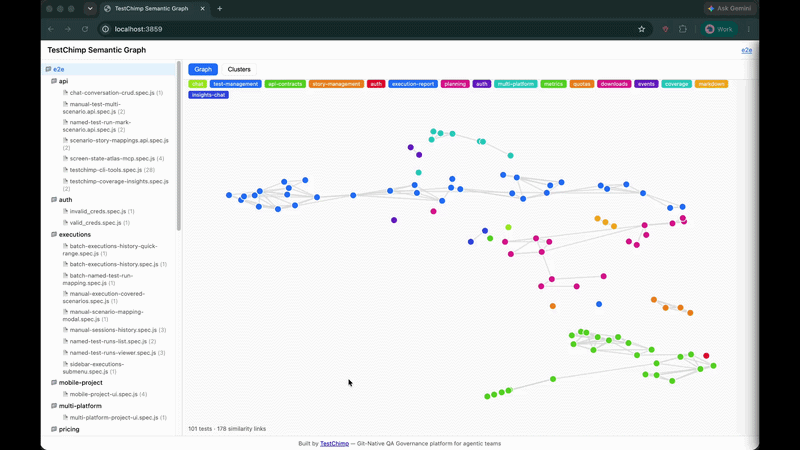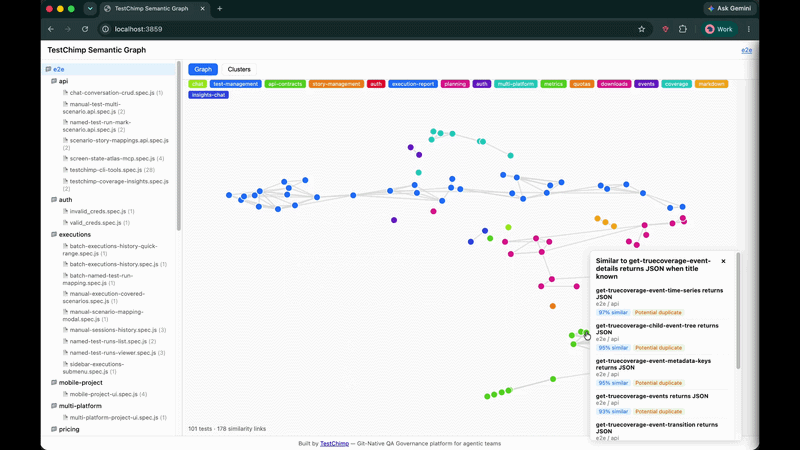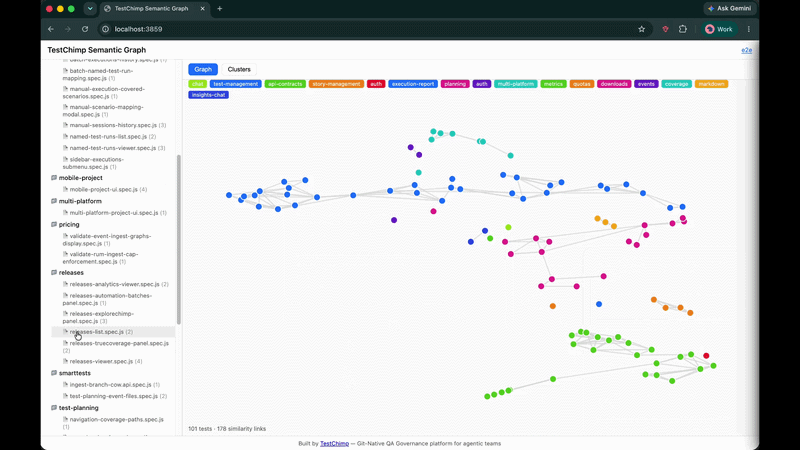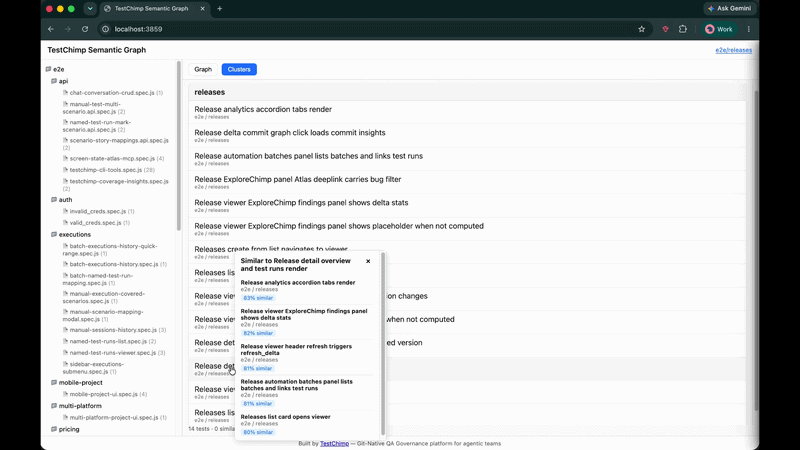
Semantic Graph visualization — folder tree, 2D similarity graph, and cluster list view


The new problem: agents author tests en masse​

For most of the last decade, the hard part of E2E testing was throughput: humans could not write and maintain enough tests to keep up with product velocity.

That constraint is collapsing. With Claude Code, Cursor, and agent skills like the TestChimp skill, a single prompt can produce a folder of well-formed Playwright specs in minutes. Coverage gaps that used to take a sprint to close can shrink to an afternoon.

The bottleneck has moved.

EraPrimary constraintWhat "good" looked like
Manual QAAuthoring speedEnough tests to cover the happy path
Human + low-code toolsUI-layer setup frictionStable POMs, fewer flakes
Agentic QASuite quality at scaleDistinct, high-signal tests—not copies

When an agent is rewarded for adding tests—closing coverage gaps, responding to PR feedback, or filling in scenarios from a test plan—it has no innate sense of "this already exists, slightly reworded." Left unchecked, suites balloon with:

  • Duplicate tests that assert the same behaviour under different titles
  • Near-duplicates that differ only in fixture data or selector phrasing
  • Clustered redundancy where five tests all exercise the same checkout edge case
  • Invisible overlap across folders, because no human (and no agent) holds the entire suite in working memory

This is the QA equivalent of boiling the lake in the wrong direction: lots of heat, little new coverage. Worse, duplicate tests inflate CI time, confuse failure triage, and give a false sense of depth—your line count grows while your behavioural breadth stalls.

The question is no longer "Can we write more tests?" It is:

"Are we writing useful, distinct tests—or just duplicative ones?"

That question needs a semantic answer, not a filename diff.


What is Semantic Graph?​

Semantic Graph is an open-source tool from TestChimp that maps your Playwright test suite by meaning, not syntax.

It is published as @testchimp/semantic-graph on npm and lives in the TestChimp/semantic-graph repository. Run one command against your tests directory; the CLI:

  1. Scans *.spec.ts, *.test.ts, and related Playwright files
  2. Parses each test's suite path, title, intent comments, scenario annotations, and body
  3. Embeds the canonical test text with an embedding model (OpenAI or Voyage AI)
  4. Clusters tests by semantic similarity using DBSCAN
  5. Lays out a 2D graph with UMAP so similar tests appear close together
  6. Names clusters with a lightweight LLM pass (e.g. "auth", "checkout", "api-contracts")
  7. Serves a local interactive UI at http://localhost:3859

No database. No TestChimp account required. Embeddings are computed in memory each run—ideal for local audits, pre-merge reviews, or giving an agent a structural view of the suite before it authors more tests.


How it works (the pipeline)​

Understanding the pipeline helps you interpret the graph—and tune how agents use it.

1. Parse tests into embedding-ready text​

The core library (@testchimp/semantic-graph-core) includes a vendored Playwright-aware parser. For each test it builds canonical text:

Suite: checkout > guest flow
Test: rejects expired coupon at payment step
Body:
Scenario: Guest checkout with invalid coupon
// intent: verify error copy and no charge created
await page.goto('/checkout');
...

Parsing captures intent comments and scenario annotations—the same metadata agents should be authoring anyway when following requirement traceability conventions. Two tests with different selectors but the same intent will land close together in embedding space.

2. Embed with cosine similarity​

Each test's text is sent to an embedding API in batches (default model: text-embedding-3-small for OpenAI, voyage-4 for Voyage). The tool computes cosine similarity between vectors and applies configurable thresholds:

SignalDefault thresholdMeaning
Graph edge≥ 0.75Tests are semantically related
Similar≥ 0.80Worth reviewing together
Potential duplicate≥ 0.92Strong dedup candidate

These thresholds mirror how humans judge redundancy: not byte-identical, but "would a failure in one make the other pointless?"

3. Cluster with DBSCAN​

Similar embeddings are grouped with DBSCAN density clustering—no need to pick k clusters upfront. Each cluster gets an LLM-generated label (e.g. "settings-page", "admin-tasks") so the legend is readable at a glance.

4. Visualize with UMAP + D3​

A seeded UMAP projection maps high-dimensional embeddings to 2D coordinates. The bundled UI (built with D3.js) renders:

  • Graph view — nodes as tests, edges as similarity links; click a node to see nearest neighbours and duplicate flags
  • Clusters view — grouped list with colour-coded legend
  • Folder tree — scope the graph to a directory or single file

Zoom into tests/checkout/ before a refactor. Scan the whole suite before a release. Hand the URL to an agent and ask it to propose merges.


Why this matters for agentic QA workflows​

Semantic Graph is not a replacement for TrueCoverage—production-informed prioritization—or requirement traceability. It solves a orthogonal problem: intra-suite redundancy.

Here is where it fits in a modern agent loop:

Before the agent writes​

Run Semantic Graph and attach the cluster summary to the agent's context. Instructions become concrete:

"We already have four tests in the checkout cluster covering coupon validation. Do not add another unless you are testing a different failure mode."

This is cheaper and more reliable than asking the agent to grep test titles.

After the agent writes​

Re-run the graph on the PR branch. New nodes that snap onto existing clusters—or spike duplicate scores above 0.92—are review flags. Pair with CI the same way you gate on lint or coverage deltas.

During suite health reviews​

Quarterly "suite diet" sessions used to mean spreadsheets and gut feel. Now: filter to clusters with high internal similarity, merge or delete, and measure CI time recovered.

Complement to production signals​

TrueCoverage tells you what behaviours users need tested. Semantic Graph tells you whether your existing tests are saying the same thing twice. Both are necessary for a suite that is broad and lean.


What you see in the UI​

The demo above shows the full workflow:

  1. Left panel — folder tree mirroring your repo layout; click a folder or file to scope the view
  2. Graph mode — force-directed layout; proximate nodes are semantically alike
  3. Clusters mode — tests bucketed with named themes
  4. Popover — click any test to see top similar neighbours, similarity scores, and potential duplicate badges

The UI ships inside the npm package—no separate install. It is the same "freebie" static app published as @testchimp/semantic-graph-viz in the monorepo for anyone who wants to embed or fork it.


Try it yourself​

Prerequisites​

  • Node.js 18+
  • An API key for embeddings (and cluster naming):
    • OpenAI — one key covers embeddings + LLM, or
    • Anthropic + Voyage — Claude for cluster labels, Voyage for embeddings (Anthropic does not ship an embedding API)

Quick start (OpenAI)​

export PROVIDER=openai
export API_KEY=sk-...

npx @testchimp/semantic-graph visualize --tests-dir ./tests

Open the printed URL (default port 3859). Add --verbose for embedding progress and diagnostics.

Claude + Voyage​

export PROVIDER=anthropic
export API_KEY=sk-ant-...
export VOYAGE_API_KEY=pa-...

npx @testchimp/semantic-graph visualize --tests-dir ./tests

All options​

FlagDescription
--tests-dir <path>Root folder to scan (required)
--port <n>Listen port (default 3859)
--verbose / -vDiagnostics to stderr

See the README for environment variables, monorepo build instructions, and npm publish details.


Continuous governance with TestChimp​

Semantic Graph is deliberately local and standalone—a flashlight you can shine on any Playwright repo, TestChimp customer or not.

For continuous duplicate detection, requirement traceability, release confidence, and keeping suites healthy as agents keep authoring, see TestChimp—the git-native QA governance platform built for agentic teams. Install the TestChimp Agent Skill and run /testchimp test after each PR to orchestrate coverage, exploration, and plan alignment in one loop.


FAQ​

What test file types are supported?​

The scanner picks up *.spec.ts, *.spec.js, *.test.ts, *.test.js, and .mjs / .cjs variants under your chosen root—standard Playwright test layouts.

Does it require a TestChimp account?​

No. Semantic Graph runs entirely locally. You only need embedding (and optionally LLM) API keys.

How is this different from code coverage?​

Code coverage measures which lines executed. Semantic Graph measures whether test intentions overlap. A suite can have high line coverage and still be full of redundant scenarios.

How is this different from duplicate detection by test name?​

Titles lie. Agents especially love paraphrasing: "should reject invalid coupon" vs "guest user sees error for expired promo code." Embeddings capture the full body and intent, not the string on line one.

Can I use it in CI?​

Today the primary interface is the local visualize command and JSON APIs (/api/graph, /api/similar). For CI gates, parse the API responses or run before review and archive the graph output. Continuous server-side governance is on the TestChimp platform roadmap.

What embedding models are supported?​

Defaults: text-embedding-3-small (OpenAI) and voyage-4 (Voyage). Override with EMBEDDING_MODEL. LLM cluster naming defaults to gpt-5-nano or claude-3-5-haiku-latest.

Is the source code open?​

Yes. MIT-licensed monorepo: github.com/TestChimp/semantic-graph. Packages: @testchimp/semantic-graph-core, @testchimp/semantic-graph, @testchimp/semantic-graph-viz.


Summary​

Agentic QA solved test authoring at scale. The next discipline is test distinctness at scale—ensuring every new spec adds behavioural breadth, not noise.

Semantic Graph gives you a semantic map of your Playwright suite: embeddings for meaning, DBSCAN for clusters, UMAP for intuition, and a local UI for humans and agents alike. Run it before you merge agent-authored tests. Run it when CI gets slow. Run it when you suspect the lake is boiling but not reducing risk.

Get started: github.com/TestChimp/semantic-graph · npx @testchimp/semantic-graph visualize


References and further reading​

Test Runs: Turn Testing Into Release Confidence

· 11 min read
Nuwan Samarasekera
Founder & CEO, TestChimp

TL;DR: TestChimp now has Test Runs—named validation campaigns that roll up scenario progress across manual sessions and automation batches. If you have used test runs in TestRail, Qase, or PractiTest, the concept will feel familiar. What is different is that scope, progress, and drill-down inherit the folder structure of your test plan—not a flat, manually curated case list copied into yet another container.

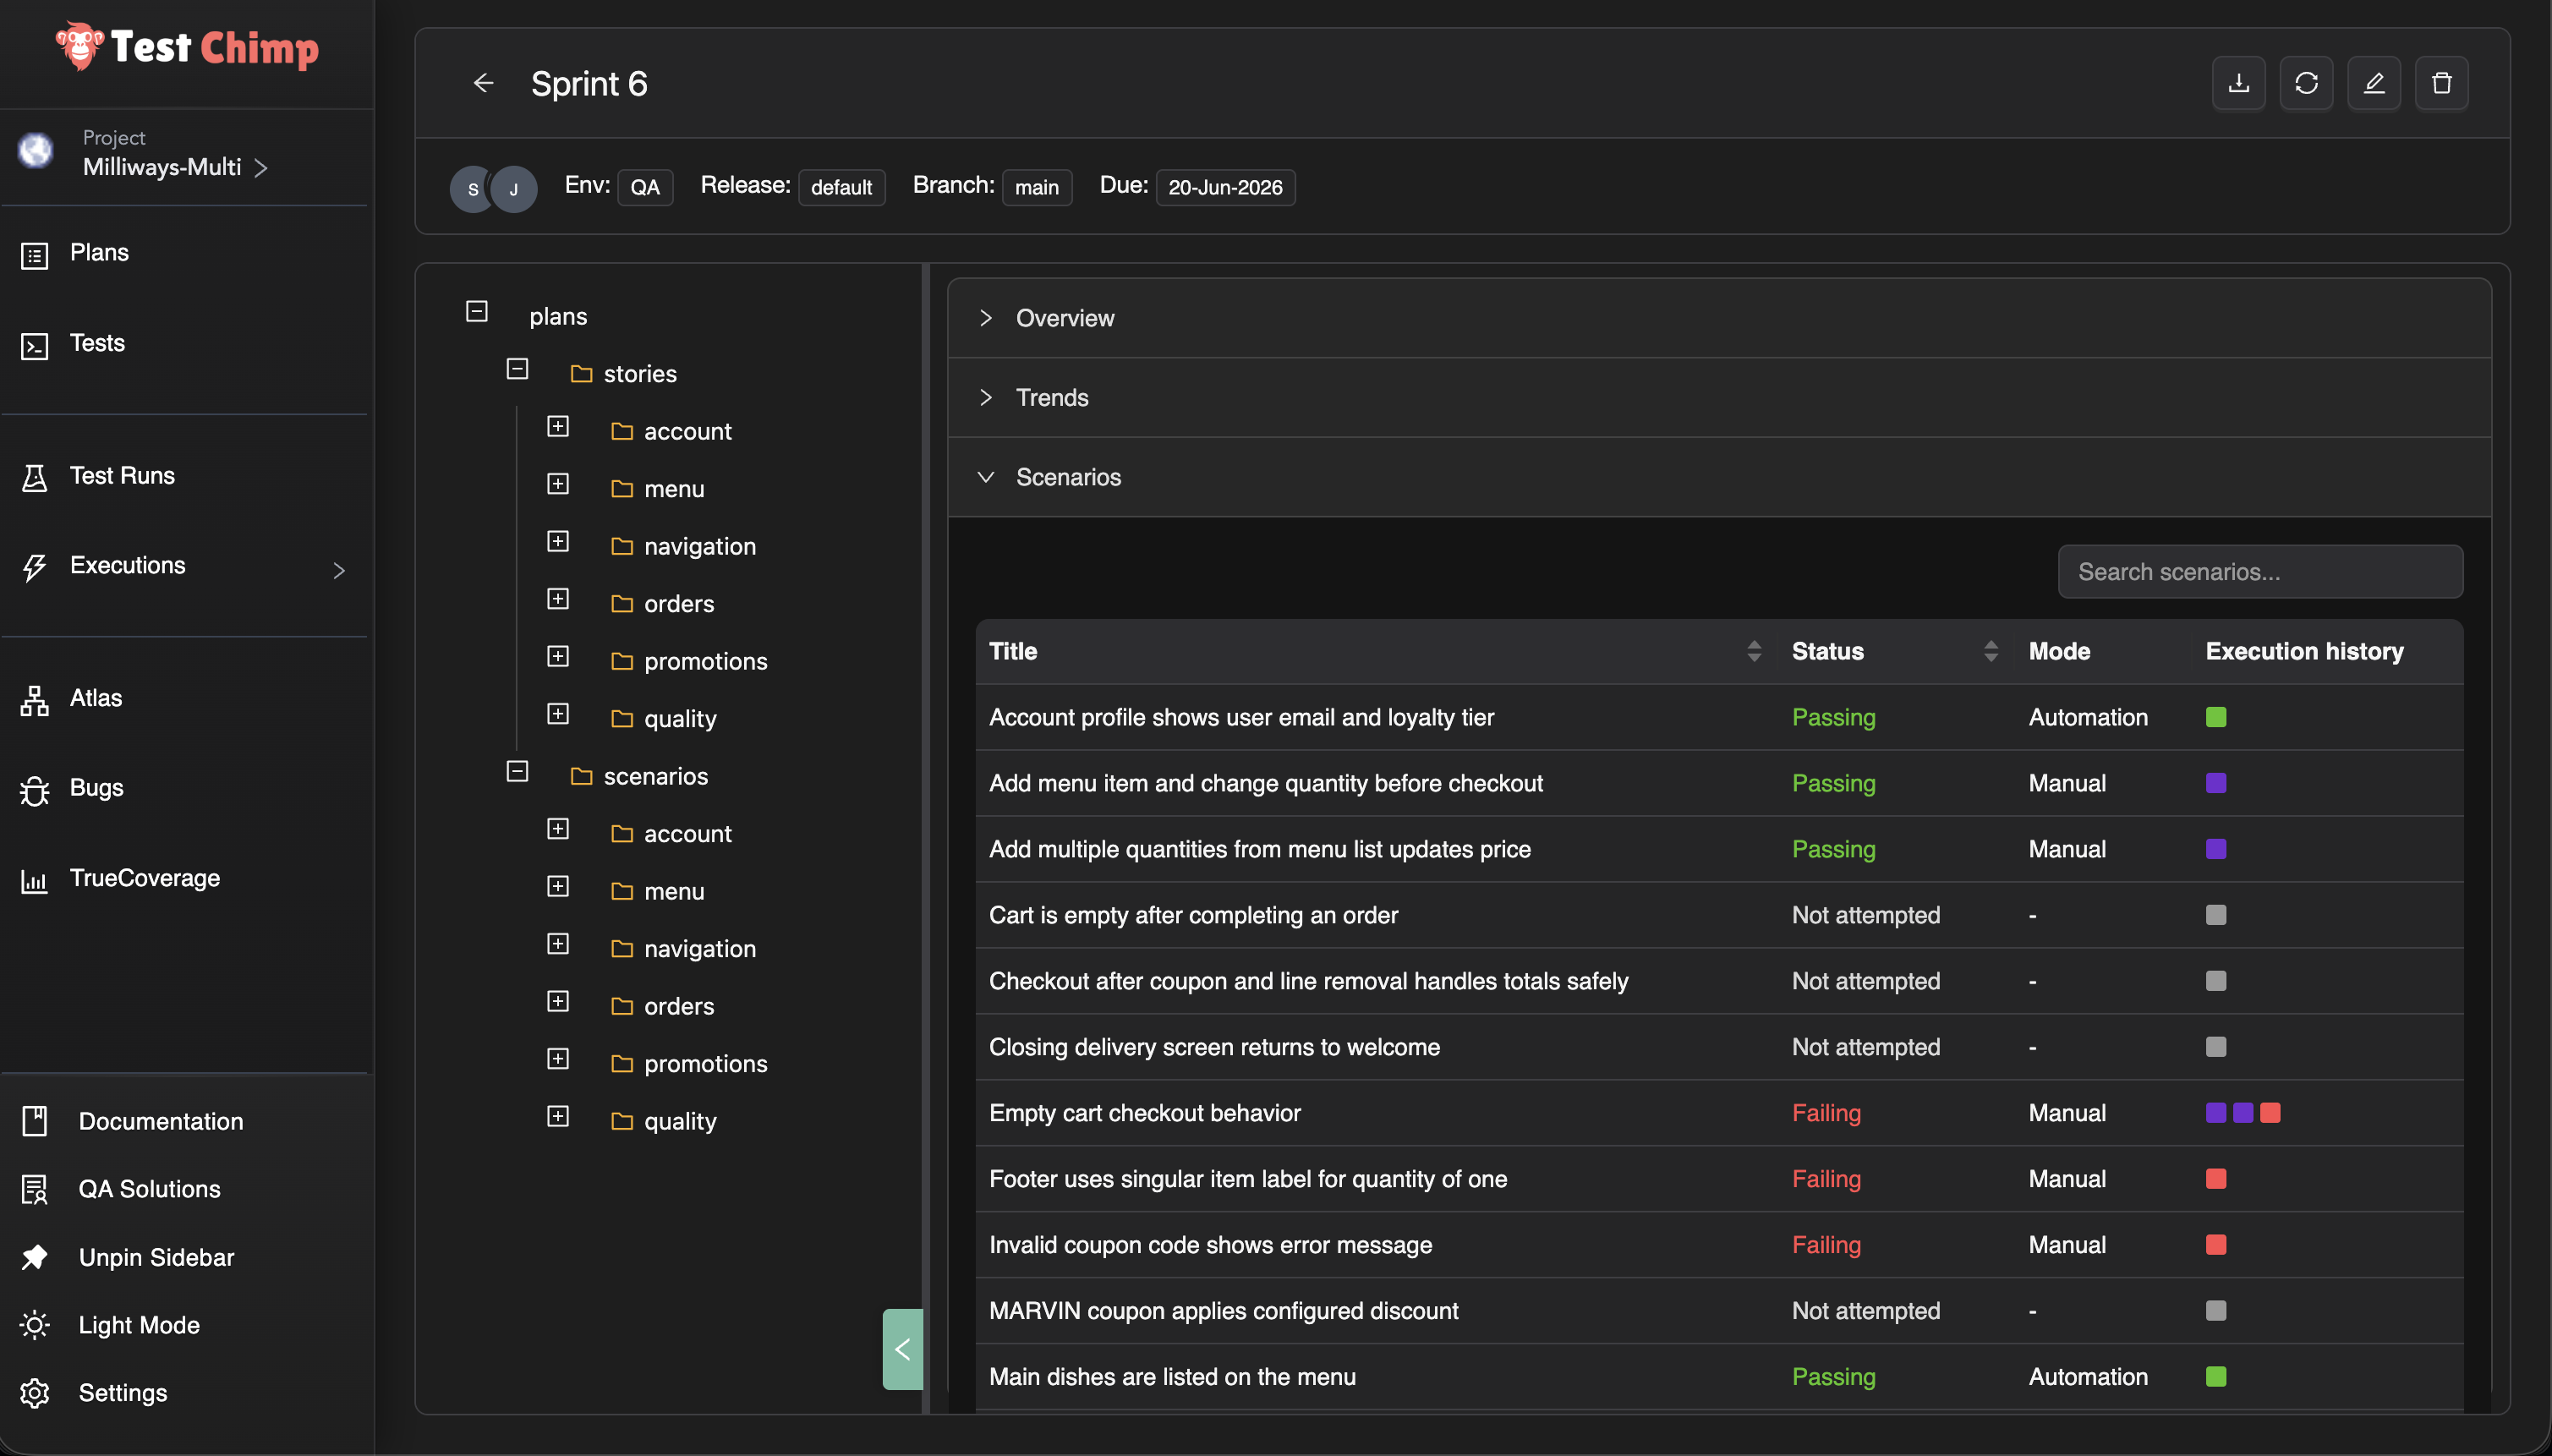
Test Run viewer — overview, trends, and folder-scoped scenario progress


What is a test run?​

In software testing, a test run is the execution of a defined set of tests against a specific version or build of the system under test. The ISTQB glossary defines it as “the execution of a test suite on a specific version of the test object.” Test execution—the process of running those tests and recording outcomes—is a core part of the fundamental test process described in ISO/IEC/IEEE 29119.

In practice, teams use test runs to answer a release question: Given the scenarios we committed to validate for this sprint or version, how far along are we—and what is still failing?

Traditional test management systems such as TestRail and Qase model a run as a container: selected test cases, assignees, pass/fail/blocked status, and often milestone or environment context. TestRail’s guidance notes that runs are typically created per sprint or release so managers can track progress in real time.

Test Runs in TestChimp preserve that coordination purpose while changing what sits underneath—the plan, the executions, and how progress rolls up.


The gap test runs are meant to close​

Most teams already know the shape of a release cycle:

  • a defined set of scenarios to validate
  • manual testers working through critical paths
  • automation running in CI on every build
  • a lead asking, “Are we done yet?”

Traditional tools answer the last question with a run—but the artifacts rarely stay connected.

User stories often live in Jira or similar issue trackers. Scenarios live in a TMS. Manual evidence sits in screenshots and Slack. Automation results sit in GitHub Actions, Jenkins, or a Playwright CI report. Requirement traceability—linking requirements to verifying tests, as described in ISO/IEC/IEEE 29148—is often maintained in spreadsheets or a test traceability matrix that goes stale.

The run becomes another manually curated list, disconnected from how the product is organized and how work actually happens.

We built Test Runs in TestChimp to close that loop without duplicating your plan in a flat case catalog.


Same concept, different foundation​

A Test Run in TestChimp is still a time-bound validation campaign: a title, optional environment and release context, collaborators, a due date, and a scope of scenarios to validate.

What changes is everything underneath.

Traditional TMS test runTestChimp Test Run
Flat list of test cases copied into the run (TestRail add_run)Scope selected from your plans folder tree (stories and scenarios)
Manual results entered in the TMS UIManual sessions linked from the Chrome extension or web UI—with step evidence
Automation results imported via API or re-entered (TestRail result import)Automation batches linked after CI Playwright runs; no duplicate result entry
Progress is case-by-case checkboxesProgress is scenario status (passing / failing / not attempted) from the latest linked execution
Roll-up is a fixed “suite” or “section”Roll-up follows any folder in your plan—checkout today, authentication tomorrow

You are not maintaining a parallel catalog. You are pointing a run at the test plan you already have.


One run, both execution types​

The most common fracture in enterprise QA is two parallel tracks:

  • manual validation tracked in a test management tool
  • automated validation tracked in CI or a vendor dashboard

Qase’s own documentation describes the tension: auto-generated CI run names pile up quickly, and teams need runs that “tell a story at a glance” when reviewing overnight failures before a release.

A Test Run in TestChimp is deliberately execution-type agnostic. Link a manual session from exploratory regression. Link tonight’s Playwright batch. Link both to the same run. Scenario status reflects the latest relevant execution—whether a human marked a session passed or CI reported a SmartTest failure.

That is the same unified coverage story we told with manual testing and traceability—now packaged for release-scale questions instead of only folder-level requirement traceability insights.


Folder-based progress, not flat lists​

Because TestChimp organizes stories and scenarios as markdown files in folders (Test Planning as Code), a test run inherits something traditional tools struggle to offer: scoped views at any granularity.

Select the root of the run and see overall progress for the whole release. Select checkout/ and see only checkout scenarios. Select a single story file and see exactly what is left on that requirement.

No re-tagging. No re-grouping cases into ad hoc suites every sprint. The folder structure you already use for planning becomes the structure you use for reporting—the same principle as coverage at any folder level in Test Planning.

That matters when:

  • feature teams own folders, not individual case IDs
  • a release spans several modules but not the entire backlog
  • you need a standup answer for one area without re-filtering a 2,000-row grid

Trend charts in the run viewer show how passing, failing, and not-attempted counts move over time—useful for daily readouts without exporting to a spreadsheet.


Why this fits the agentic era​

Test runs are not a throwback to heavyweight process. They are a lightweight coordination layer on top of artifacts agents can already read.

Your scenarios are files. Your tests link with scenario annotations (requirement traceability in code). Executions feed the same traceability graph whether they are manual or automated. A test run simply names the campaign—“Sprint 42 regression”, “v2.1 sign-off”—and gives humans a place to see progress while agents keep authoring against the same plan.

We are not replacing CI dashboards or extension manual capture. We are giving product and QA leads a single pane for this validation cycle, grounded in requirements rather than orphaned case records.


See it in action​

Using Test Runs in TestChimp — video walkthrough

For step-by-step setup—creating a run, defining scope, linking batches and sessions, reading the viewer—see Test Runs in the docs.


Frequently asked questions​

What is a test run in software testing?​

A test run is a structured execution of a selected set of tests against a specific build, release, or milestone. The ISTQB glossary defines it as running a test suite on a particular version of the system under test. Teams use runs to track who tested what, record pass/fail outcomes, and report release readiness.

How is a TestChimp Test Run different from a TestRail or Qase test run?​

The coordination goal is the same: scope a set of tests, track progress, report status. The foundation is different. Traditional tools copy flat test cases into a run container (TestRail runs, Qase test runs). TestChimp scopes runs from your existing plans folder tree and aggregates results from linked manual sessions and automation batches—without maintaining a duplicate case list.

Can one test run include both manual testing and test automation?​

Yes. TestChimp Test Runs are execution-type agnostic. Link manual sessions captured via the Chrome extension and automation batches from Playwright CI to the same run. Each scenario’s status reflects the latest linked execution, whether the outcome came from a human or from CI.

Do I need to duplicate test cases to create a test run?​

No. You select scope from folders and files already in Test Planning. Scenarios remain the same markdown artifacts your team authors and version-controls; the run is a pointer and progress lens, not a second catalog.

What is folder-based test run progress?​

Because stories and scenarios live in a nested folder structure (Test Planning as Code), the test run viewer lets you drill into any folder or file and see passing, failing, and not-attempted counts for just that subtree. Root shows the full run; authentication/ shows auth only—without re-tagging cases or rebuilding suites each sprint.

How do Test Runs relate to requirement traceability?​

Requirement traceability links requirements and scenarios to executions over time—supporting the verification relationships described in standards such as ISO/IEC/IEEE 29148. Test Runs add a named campaign layer: a due date, collaborators, explicit scope, and release-oriented progress for one validation cycle. Traceability is ongoing product health; test runs are this regression or this release sign-off.

When should we use test runs vs Test Planning insights alone?​

Use Test Planning insights when you want continuous coverage visibility for a folder, environment, and time range. Use Test Runs when you need a time-bound campaign with assigned collaborators, a due date, and a dedicated dashboard fed by executions you link during that cycle—similar to how teams use TestRail test runs per sprint, but unified across manual and automated work.

Yes. Automation batches can be linked from Executions → Automation Batches (list or batch viewer). Manual sessions can be linked at capture time in the extension or afterward from the manual session viewer. Many-to-many linking is supported—a batch or session can belong to multiple active runs.


Try it​

Open Test Runs from the TestChimp sidebar, create a run scoped to the folder your team owns, and link the next manual session or automation batch you execute.

If you are comparing approaches, our requirement traceability post explains the foundation; this feature adds the campaign layer on top when you need to track a specific release or regression cycle end to end.

We are iterating on collaborator workflows, PDF reporting, and deeper agent integration. Feedback welcome—especially from teams migrating off TestRail-style run models.


Further reading​

TestChimp

Test management & QA concepts

Automation & CI

Related posts

TestChimp Partners with Bunnyshell

· 4 min read
Nuwan Samarasekera
Founder & CEO, TestChimp

As AI coding agents become more prevalent, they are changing more than just how code gets written.

They're changing when software should be tested.

Today, we're excited to announce our partnership with Bunnyshell to bring PR-scoped ephemeral environments directly into the AI-powered QA workflows executed by TestChimp.

This partnership solves a problem that is becoming increasingly common as organizations adopt AI-assisted development at scale.

Bunnyshell Partnership Announcement

The Hidden Challenge of AI-Driven Development​

AI dramatically increases PR volume.

Not only are there more pull requests being created, but those pull requests often contain substantially more changes than their human-authored counterparts.

Historically, many teams followed a workflow similar to this:

  1. Developers create PRs
  2. PRs are merged into the main branch
  3. A release is deployed to a shared staging environment at end of sprint
  4. QA validates the release

This workflow worked reasonably well when development velocity was constrained by human output.

However, as AI agents begin generating code continuously, several problems emerge:

  • More PRs are merged between testing cycles
  • Individual PRs contain more changes
  • Regressions become harder to isolate
  • Root-cause analysis becomes increasingly expensive

By the time QA identifies a problem in staging, the issue may have originated from one of dozens of recently merged pull requests.

  • Finding the offending change becomes a detective exercise.
  • Reverting safely becomes difficult.
  • Confidence in releases decreases.

The Solution: E2E tests in each PR​

What if every PR was E2E tested before it reaches the main branch?

Ideally, every PR should arrive with:

  • New end-to-end tests
  • Updates to existing affected tests
  • Validation that those tests pass
  • Evidence that the feature behaves as intended

This significantly reduces the amount of uncertainty that accumulates in shared environments.

The challenge, of course, is environment availability. To test a PR, you need an environment that actually contains the PR's changes. Note just a frontend (like what firebase / vercel provide) - but full-stack isolated environment.

For small applications, developers can often spin everything up locally. For larger systems, that quickly becomes impractical.

This is exactly where Bunnyshell shines - ephemeral environments, spun up at lightning speed - deployed on the cloud.

How Bunnyshell Solves the Environment Problem​

Bunnyshell allows teams to define their application infrastructure using a simple YAML specification.

Think of it as a blueprint describing everything required to run your application:

  • Frontend
  • Backend services
  • Databases
  • Networking
  • Environment variables
  • Dependencies between services

Once this blueprint exists, Bunnyshell can automatically provision isolated environments on demand - and deploy them to your K8s cluster. Don't worry - TestChimp SKILL transitively loads Bunnyshell skill and authors the YAML file for your infrastructure.

Instead of testing changes in a shared staging environment, every pull request receives its own dedicated clean environment for agents to work on.

  • No shared environment.
  • No interference from other testing work (manual testing / other test suites running etc.).
  • No waiting for deployment windows.

When you run "/testchimp test" workflow, TestChimp can now provision an ephemeral environment via your Bunnyshell config - scoped to the current PR, load up necessary test data through already defined fixtures, and execute testing on this environment.

Result: You can now merge your agent authored PR with confidence.

This partnership brings together two complementary capabilities crucial for QA shift-left paradigm:

Bunnyshell provides isolated, production-like environments for every pull request.

TestChimp provides AI-powered exploration, validation, and automated test creation.

Together, they enable a workflow where every PR can be validated in isolation before it reaches main.

The icing on the cake: TestChimp users will get 15% off their Bunnyshell bills!

Simply use code: TESTCHIMP15 when signing up.

Manual Testing with Traceability

· 5 min read
Nuwan Samarasekera
Founder & CEO, TestChimp

:::tip Updated workflow Since this post, the extension also supports open-ended sessions (objective instead of scenario), Add bug on steps (deferred until session finish), and Atlas-backed screen/state selection. See the current guide: Manual test session capture. :::

Manual testing is still where teams catch the “this feels wrong” stuff:

  • confusing UX
  • copy bugs
  • edge-case flows
  • integration weirdness that doesn’t show up in clean scripted runs

But there’s a persistent problem: manual testing evidence doesn’t stay connected to what was planned.

Test plans live in one place. Notes and screenshots live in another. Pass/fail outcomes live in Slack threads or Jira comments. And the mapping back to the scenario is usually… memory.

Today we’re announcing a new workflow in TestChimp: Manual testing with traceability.


The idea​

If your team already does test planning (user stories → scenarios), then manual execution should be:

  • tied to a specific scenario
  • captured as step-by-step evidence
  • recorded with environment + release context
  • marked passed / failed
  • queryable later as execution history (not a dead document)

That’s what this feature does.


Manual Test Session Capture (in the Chrome extension)​

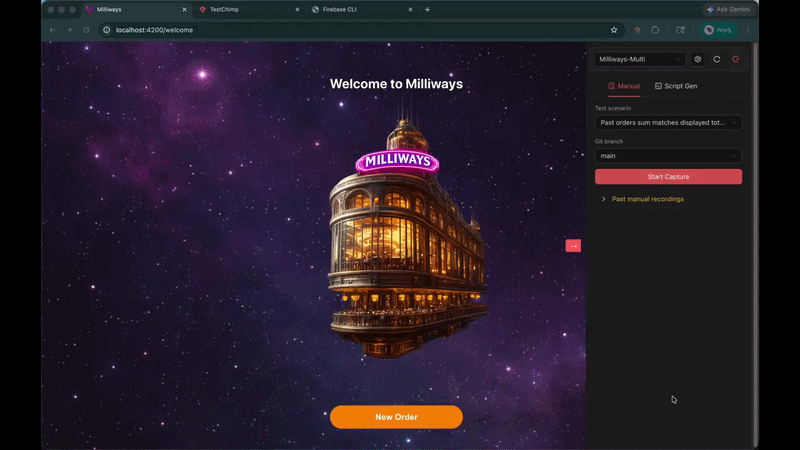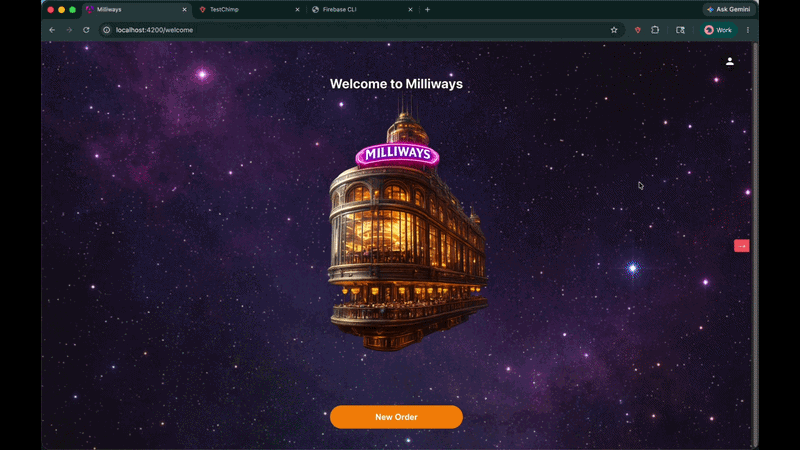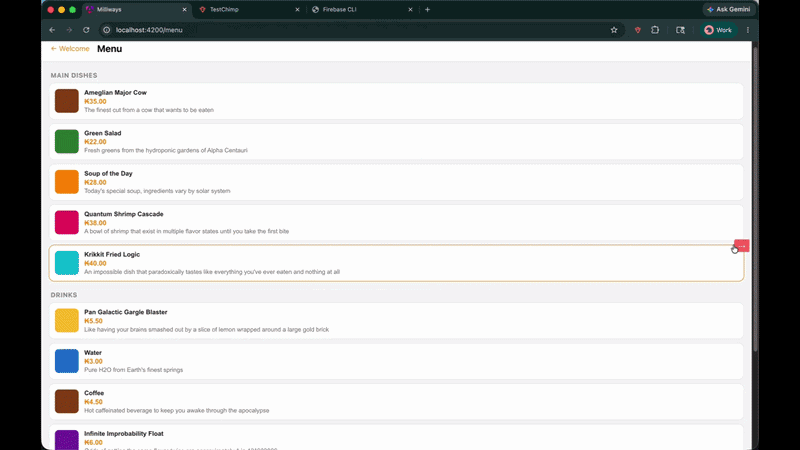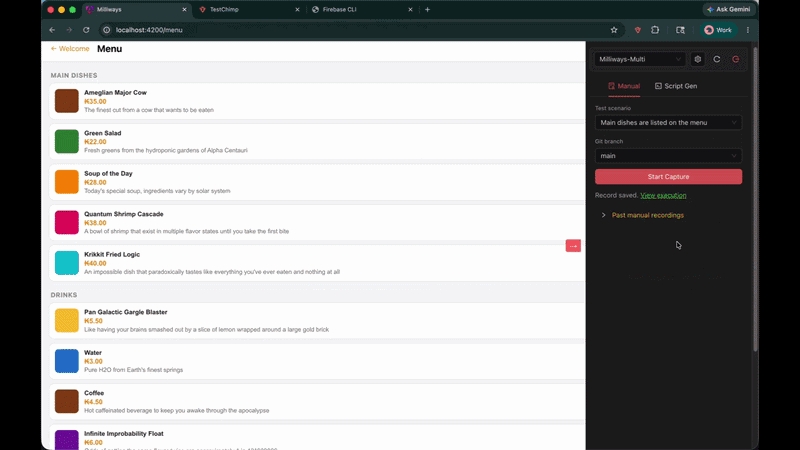
In the TestChimp Chrome extension, there’s now a Manual tab.

It lets a tester record a manual session while they execute a planned scenario, with traceability stored directly on the record.

Manual test session capture

What gets captured:

  • Steps: each interaction is captured as a step
  • Screenshots: uploaded automatically
  • Notes: add notes to the latest step, optionally highlighting a UI element/area
  • Outcome: mark the session as passed or failed
  • Context: environment + release (and optional git branch context)

How it works (quick walkthrough)​

  1. Open the Chrome extension and switch to the Manual tab
  2. Click Create Manual Test Record
  3. Select the test scenario you’re executing (required)
  4. (Optional) pick the git branch context
  5. Click Start Capture and run the test as usual
  6. Add notes when needed (with optional element/area attachments)
  7. Click End capture, then mark passed or failed
  8. Open View execution to see the full record in TestChimp

If you want the full documentation, see Manual Test Session Capture.


Why this matters (beyond “we captured a GIF”)​

Manual testing isn’t going away. But it needs to stop being unstructured.

With scenario-linked manual records, you can answer real questions without archaeology:

  • Which scenarios were manually executed for this release?
  • Where are we relying on manual validation because automation doesn’t exist yet?
  • What’s the evidence behind a “pass” when something regresses later?
  • What’s failing on a specific branch or environment?

It’s manual testing… but operationalized.


Unified coverage: manual + automated, in one view​

The bigger win is what happens after you capture manual execution.

Because manual sessions are linked to the same scenarios as your SmartTests, TestChimp can provide unified requirement coverage insights across:

  • Automated runs (SmartTests in CI or in the Web IDE)
  • Manual runs (scenario-linked manual sessions with evidence + pass/fail)

So instead of two separate worlds (a test management tool for manual, and CI dashboards for automation), you get one requirement-centric view:

  • scenario coverage status
  • recent execution history (pass/fail)
  • evidence trail for manual validation
  • clear gaps where scenarios have no automated coverage yet

This is the foundation for keeping your suite honest: manual validation is visible and it doesn’t get conflated with “we have automation”.


How coding agents consume this to prioritize test authoring​

Once coverage and history are unified at the scenario layer, agents can treat it as an ordered backlog—especially in workflows like /testchimp test (PR-level) and /testchimp evolve (portfolio-level).

In practice, the agent pulls:

  • Requirement coverage (what scenarios are covered vs missing tests)
  • Execution history (what’s failing or flaky right now)
  • (Optionally) TrueCoverage signals (what real users do most, where they drop off)

Then it prioritizes authoring work where it has the highest leverage:

  • uncovered high-priority scenarios first
  • gaps in the exact folder/feature area the team owns
  • high-traffic paths with low coverage (when TrueCoverage is enabled)

The end result is a tighter loop: manual + automated executions feed the same insights, and those insights drive agents toward the most important missing tests—rather than “write more tests” as a generic goal.


Manual capture vs SmartTest authoring​

Manual capture creates an auditable execution record (pass/fail, notes, screenshots). To turn that session into a Playwright SmartTest, use Copy test generate prompt after capture and paste it into your TestChimp-skilled agent (creating SmartTests from the browser).


Try it​

  • Install the Chrome extension
  • Plan scenarios in Test Planning
  • Run your next manual regression session through the extension

If you have feedback on what would make manual execution records more useful (branch/release filtering, richer notes, better rollups), we’re actively iterating.